Code Mode
CodeMode replaces individual tool calls with a single sandboxed Python execution environment. Instead of the model issuing one tool call per action, it writes a Python program that calls your tools as functions — with loops, conditionals, variables, and asyncio.gather — all inside a sandboxed Monty runtime.
While Pydantic AI Harness is on 0.x releases, the API may change between minor releases; when it does, deprecation warnings and release-note migration guidance tell you (or your agent) exactly how to upgrade. See the version policy.
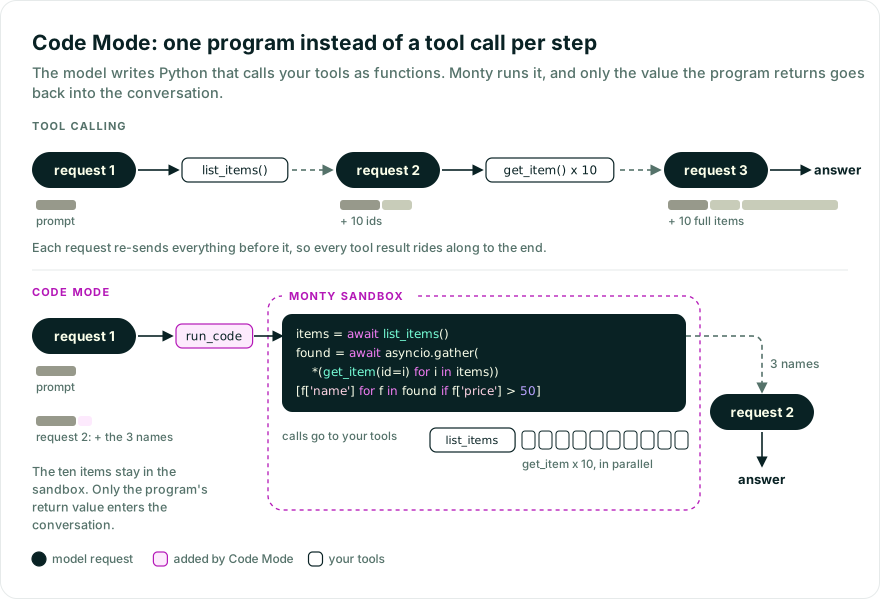
Standard tool calling often needs another model turn for each dependent batch of tool calls. An agent that needs to fetch 10 items and then process their results can require many model turns, increasing latency, cost, and context use. Intermediate results also grow the conversation history.
CodeMode wraps eligible tools into a single run_code tool. The model writes sandboxed orchestration code that fans calls out with asyncio.gather, filters and transforms results, and returns only what matters. Calls from that code are dispatched through Pydantic AI to the host tools.
| Standard tool calling | Code mode |
|---|---|
| Dependent tool batches across model turns | Many dependent calls in one run_code |
| Parallel only when the model emits a batch | Parallelism expressed in Python |
| No local computation | Filter, transform, aggregate in code |
| Large conversation history | Compact — fewer messages |
Durable execution integrations can record nested calls for deterministic replay.
IPython Code Mode offers the same run_code tool backed by a persistent IPython kernel instead of Monty. Pick by where the agent runs:
| Code Mode | IPython Code Mode | |
|---|---|---|
| Built for | Production and web-facing agents | Local agents you trust to do whatever the code asks |
| Safe in a webserver | Yes | No, unless the agent runs in a sandbox |
| Python | The Monty subset, with time and memory limits | Full CPython, with any installed package |
| Filesystem and network | Only through mount, os_access, and tools | Unrestricted, with the agent process’s permissions |
| State | Per run, plus an optional repl_store | A kernel per run, or one IPythonKernel kept across runs |
Code mode requires the Monty sandbox, available via the codemode extra (the code-mode extra is an equivalent alias):
pip install "pydantic-ai-harness[codemode]"
uv add "pydantic-ai-harness[codemode]"
Construct an Agent with CodeMode() in its capabilities, then register tools as usual. Every eligible regular tool becomes callable from inside run_code:
from pydantic_ai import Agent
from pydantic_ai_harness import CodeMode

agent = Agent('anthropic:claude-sonnet-5-5', capabilities=[CodeMode()])


@agent.tool_plain
def get_weather(city: str) -> dict:
    """Get current weather for a city."""
    return {'city': city, 'temp_f': 72, 'condition': 'sunny'}


result = agent.run_sync("What's the weather in Paris and Tokyo, in Celsius?")
print(result.output)
Inside a single run_code call, the model writes code like the following (illustrative — the exact code the model emits will vary):
import asyncio

paris, tokyo = await asyncio.gather(
    get_weather(city='Paris'),
    get_weather(city='Tokyo'),
)
paris_c = round((paris['temp_f'] - 32) * 5 / 9, 1)
tokyo_c = round((tokyo['temp_f'] - 32) * 5 / 9, 1)
{'paris': paris_c, 'tokyo': tokyo_c}
Both weather lookups run in parallel and the conversions run inside Monty, all within one run_code call.
By default, CodeMode(tools='all') sandboxes every eligible regular tool. Framework control tools, undiscovered deferred tools, native fallbacks, and other code-execution tools remain native. Shell surfaces count as code-execution tools: Shell’s run_command and start_command sit beside run_code rather than inside it, so the model never has to quote a shell command inside a generated Python string. CapabilityCreation’s author_capability stays native for the same reason: its argument is a complete Python module. Their non-command tools (read_file, check_command, and so on) are folded into run_code like any other tool. A host that wants a code-execution tool folded anyway sets FOLD_INTO_CODE_MODE ('fold_into_code_mode', from pydantic_ai_harness.code_mode) to True in its metadata, for example from prepare_tools; the tool keeps its code_arg_name, so instrumentation and other capabilities still see it as code. The tools field is a Pydantic AI ToolSelector, so you can control which eligible tools go through the sandbox. Tools that match the selector become callables inside run_code; non-matching tools stay visible to the model as regular tool calls.
from pydantic_ai_harness import CodeMode

# By name -- only these tools are available inside run_code
CodeMode(tools=['search', 'fetch'])

# By predicate -- (ctx, tool_def) -> bool | Awaitable[bool]
CodeMode(tools=lambda ctx, td: td.name != 'dangerous_tool')

# By metadata -- combine with SetToolMetadata or a toolset's .with_metadata()
CodeMode(tools={'code_mode': True})
Use metadata when the decision should travel with a tool or toolset, rather than with one CodeMode instance. This suits shared toolsets: the toolset author tags the tools that are safe and useful to call from generated code, and each agent opts into that tag with CodeMode(tools={...}).
CodeMode(tools={'code_mode': True}) uses the standard Pydantic AI ToolSelector metadata form. A tool is sandboxed when its ToolDefinition.metadata contains all of the selector’s key-value pairs. Extra metadata on the tool is fine, and nested dictionaries are matched by deep inclusion.
The common pattern is to tag an entire toolset with .with_metadata(...):
from pydantic_ai import Agent
from pydantic_ai.toolsets import FunctionToolset
from pydantic_ai_harness import CodeMode


def search(query: str) -> str:
    """Search the web."""
    return f'results for {query}'


def fetch(url: str) -> str:
    """Fetch a URL."""
    return f'contents of {url}'


search_tools = FunctionToolset(tools=[search, fetch]).with_metadata(code_mode=True)

agent = Agent(
    'anthropic:claude-sonnet-5-5',
    toolsets=[search_tools],
    capabilities=[CodeMode(tools={'code_mode': True})],
)
Here search and fetch are removed from the model-facing tool list and become callable functions inside run_code. Tools without metadata['code_mode'] == True stay visible as regular tool calls.
When you mark tools or whole toolsets defer_loading=True (Tool Search), CodeMode keeps them out of run_code while they’re undiscovered and leaves their discovery to Tool Search; how they’re offered until then depends on dynamic_catalog, below. CodeMode uses RunContext.is_tool_available to follow that reveal state. Once the model discovers a tool — or loads the deferred capability that owns it — CodeMode folds it into run_code like any other tool from then on, so it’s callable from generated code. (The tool keeps defer_loading=True, which records what its author asked for; what changes is its availability for the run.)
By default (dynamic_catalog=True), a discovery appends to the conversation instead of rewriting it, so the prompt cache survives it. The catalog of sandboxed-tool signatures goes into the agent instructions rather than run_code’s description, as a dynamic InstructionPart with the id toolset:code_mode:catalog and on_change='append': when a discovery adds a function, the updated catalog is appended to the message history. When Tool Search found the tool, a short system prompt part sent through ctx.enqueue also names the new functions; loading a capability appends only the catalog update. Deferred tools that run_code will take over are kept off the wire until they’re found: the model finds them with the local search_tools tool, or by loading the capability that owns them, and from then on calls them from run_code only. The tool definitions and the instructions of earlier requests stay as they were sent.
The catalog renders tool definitions into the instructions, including the names, descriptions and schemas an MCP server supplies. Tool definitions are trusted operator configuration: the model already receives them in the request’s tool definitions with the same authority, so moving them into instructions gives them no authority they didn’t have. Connect only MCP servers you trust. The discovery announcement names functions only by their Python identifiers, and keeps the tool names as found in its metadata.
The cache stays intact only if a callable tools selector gives the same answer for a tool before and after it’s revealed. A selector that keeps a hidden tool native and sandboxes it once revealed declares the tool and then drops the declaration, which moves the cached prefix, as with dynamic_catalog=False.
The catalog block is keyed through the toolset id code_mode, which CodeModeToolset takes only with dynamic_catalog=True. If the agent has another toolset with the id code_mode that contributes instructions, the run raises a UserError for the duplicate id. Rename that toolset.
When a tools selector sandboxes some deferred tools and keeps others native, the local search_tools searches all of them, and the provider’s native tool search isn’t sent. Neither kind is declared before it’s found: a sandboxed tool joins the catalog, and a native one is added the way any tool found by search_tools is, which on Anthropic and OpenAI Responses appends it to the conversation. The cost is that in this setup the native tools are found by local keyword matching (or your strategy callable) rather than by the provider’s server-side search.
The 'bm25' and 'regex' Tool Search strategies have no local search_tools, so only the provider’s native tool search can find a deferred tool there. With them, a deferred tool that run_code will take over is still declared natively, and the declaration is dropped when it moves into run_code, as it is with dynamic_catalog=False.
Pass dynamic_catalog=False to keep the catalog in run_code’s description instead, which earlier releases did by default:
from pydantic_ai_harness import CodeMode

CodeMode(dynamic_catalog=False)
The tool definitions are part of the cached prompt prefix, so each discovery grows run_code’s description and invalidates the cached prefix from that point on (turns with no discovery stay cache-warm). Deferred tools are declared to the provider’s native tool search where there is one.
To keep a Tool Search corpus fully native instead — never folded into run_code, but not callable from inside it — exclude it with a tools selector; corpus members carry with_native set to the managing native tool:
from pydantic_ai_harness import CodeMode

CodeMode(tools=lambda ctx, td: td.with_native is None)
The last expression in the snippet is automatically captured as the return value — the model does not need to print(). An assignment stores a value in the REPL but does not return it. A final expression that evaluates to None is also treated as no result. Without a non-None final expression or print output, run_code returns {}. Put the assigned name on the final line:
result = await get_weather(city='Paris')
result
Reserve print() for supplementary logging: printed text is surfaced separately, wrapped alongside the last-expression result.
| Scenario | Return |
|---|---|
Non-None final expression with no print output | Last expression value |
Final assignment or None result with no print output | {} |
Print output with no final expression or a None result | {'output': '<printed text>'} |
Print output with a plain, non-None final expression | {'output': '<printed text>', 'result': <last expression>} |
| Multimodal final expression with no print output | Returned natively for model processing |
| Print output with a multimodal final expression | List with printed text followed by native multimodal content |
When a nested tool returns a ToolReturn, the snippet receives its return_value. Its content, such as a screenshot, never enters the sandbox: it is sent to the model alongside the run_code result, in call order, just as it would be for a direct tool call.
Printed output is limited to 10 MiB. Exceeding the limit makes run_code return a model retry.
Sandbox execution is bounded by resource_limits, which defaults to 30 seconds of execution time
and a 256 MiB heap. max_duration_secs applies to each run_code snippet: each snippet gets at most that much
sandbox time, which is what stops a runaway loop. Time spent awaiting a nested tool is
excluded. A snippet that hits the limit is stopped and its session is reset, so any variables,
imports, and definitions have to be recreated. The retry run_code returns says so and reports the
nested calls the snippet already made.
Sleeping is not execution time, so it has its own allowance of the same length: a snippet may sleep
for at most max_duration_secs in total. A sleep that would go past it raises TimeoutError in the
sandbox without waiting, and the session is kept. The allowance still applies inside a Temporal
workflow, where the execution-time limit is off; only resource_limits='unlimited' removes it.
Monty also limits cumulative suspensions with max_suspensions (default 1,000 per session).
External calls, OS callbacks, name lookups and future resolutions each consume this budget, so
it is not a tool-call count. Consecutive snippets share it. After exhaustion, further host
interactions fail, although pure Python using existing state may still work. run_code includes
the started-call summary and explicit restart guidance: inspect partial results before continuing,
since restart: true discards REPL state and replaying completed calls repeats their side effects.
There is no automatic restart or replay for exhaustion.
Nested tool calls are bounded separately by max_tool_calls, which defaults to 100 per run_code
call. The budget is reserved before each call is scheduled, so a snippet cannot dispatch more work
than it allows. A call past the budget fails at its call site inside the sandbox. A snippet that
catches the error keeps the results of the calls that already completed and can return them. A
snippet that lets it propagate gets a model retry reporting how many nested calls started,
followed by per-call detail: what each was called with, and whether it returned, did not finish, or was
denied. Calls that did not finish are included rather than filtered out, since a tool can apply a change
before it stops. That detail is bounded — arguments and results are previewed, and the list stops
at a size cap and says how many entries it left out — so a large payload cannot inflate the
retry. The reported total stays exact whether or not the list was cut, which is what tells the
model some calls are missing from what it can see. Nothing stops the model from calling those
tools again.
Override them with resource_limits={'max_duration_secs': 10, 'max_memory': 134_217_728, 'max_suspensions': 10_000} and
max_tool_calls=25. Pass resource_limits='unlimited' only when another execution boundary
supplies equivalent limits. It removes the time and memory caps, but leaves Monty’s default
suspension budget in place; suspensions cannot be unlimited.
Nested tool calls also count toward the run’s tool_calls_limit, together
with the run_code call that makes them. Each nested call is checked before it runs, counting the calls
still pending, and one that would exceed the limit ends the run with
UsageLimitExceeded, as a top-level tool call does. Catching
the error inside the snippet does not prevent this.
When CodeMode runs inside a Temporal workflow, it disables max_duration_secs, including an
explicit override. run_code is replayed in workflow code, so measuring elapsed time there could
make replay choose a different path from the recorded workflow. The memory and suspension caps still apply. Put
time-bounded work behind a Temporal activity instead.
Sandboxed tools render as async def functions, so generated code can start several calls and
await them together with asyncio.gather. Whether those calls overlap follows the run’s
parallel execution mode:
'parallel'(the default) and'parallel_ordered_events'run gathered calls concurrently.'parallel_ordered_events'only orders the result events of top-level tool calls, which nested calls do not emit. It is the modeDBOSDurabilityuses by default.'sequential'runs gathered calls one at a time, in the order the code started them.
A tool marked sequential=True renders as a plain def and runs alone in every mode: calls the
code started before it finish first.
Durable engines that record nested calls as steps number them as they start. When a tool or a
capability hook such as before_tool_execute awaits before its step starts, concurrent calls can
start their steps in a different order on recovery. Pass parallel_execution_mode='sequential' to
the durability capability to run nested calls one at a time.
State persists between run_code calls within the same agent run — variables, imports, and function definitions carry over. Pass restart: true in the tool call to reset state. If a worker crash or host-side execution failure invalidates the session, run_code returns a model retry that reports the reset and the nested calls that already started; the next snippet must recreate any required state.
Each agent run starts its own REPL, so a conversation made of several runs loses its sandbox state between them. Pass a repl_store to keep it: a run that calls run_code loads the state the store returns before its first snippet, and saves the REPL to the store when the run ends. The store is any object with async load and save methods (pydantic_ai_harness.code_mode.CodeModeReplStore), and the state is Monty’s opaque dump of the REPL. Key it by ctx.conversation_id, which stays the same across runs when you pass conversation_id or the previous run’s message_history:
from pydantic_ai import Agent, RunContext
from pydantic_ai_harness import CodeMode


class InMemoryReplStore:
    def __init__(self) -> None:
        self.states: dict[str, bytes] = {}

    async def load(self, ctx: RunContext) -> bytes | None:
        return self.states.get(ctx.conversation_id or '')

    async def save(self, ctx: RunContext, state: bytes | None) -> None:
        key = ctx.conversation_id or ''
        if state is None:
            self.states.pop(key, None)
        else:
            self.states[key] = state


agent = Agent('anthropic:claude-sonnet-5-5', capabilities=[CodeMode(repl_store=InMemoryReplStore())])
- A run that never calls
run_codeneither loads nor saves. restart: trueskips the saved state. The run then saves its new REPL, or callssave(ctx, None)when the restarted snippet failed before creating one.- A restored REPL keeps the resource limits it was saved under, so the state records the run’s resolved
resource_limits. A state saved under other limits, or one Monty cannot load, such as a truncated dump or one from an incompatible Monty version, is dropped with a logged warning, and the run starts a fresh REPL. - Monty does not authenticate a dump. Return only states your application saved, from storage no one else can write to.
- A timeout, worker crash, or cancelled snippet that resets the REPL keeps the state saved before the run, unless a later snippet in the run builds a new REPL, which is then saved. A cancelled run still saves an idle REPL.
- A store error does not fail the run: a failed
loadstarts a fresh REPL, and a failedsaveleaves the stored state as it was. A run whoseloadfailed does not save, so the next run can still restore the state it could not read, unless it usedrestart: true. Asavestill running after 10 seconds is cancelled, but work it handed to a thread may still finish, so write atomically. Each is logged as a warning. - Restored state skips the type check a fresh REPL’s first snippet gets, since the checker does not know the restored names.
- The dump holds every live value, so it can be large. To bound it, have
savedrop an oversized state and forget the old one. Withmonty_sandbox, a server that keeps sessions returns a record ID instead, which lives as long as the server keeps it, and a server that keeps nothing fails every save with a logged warning. - The store is not used under durable execution, where its I/O would run in replayed workflow code.
Normally, CodeMode waits for the model to finish writing a run_code call before it
runs any code. Set eager=True to start sooner:
from pydantic_ai import Agent
from pydantic_ai_harness import CodeMode

agent = Agent(
    'openai:gpt-6.1-sol',
    capabilities=[CodeMode(eager=True)],
)
For example, suppose the model produces this code one line at a time:
first = await fetch_item(item_id=1)
second = await fetch_item(item_id=2)
[first, second]
With eager mode, the first call to fetch_item can begin as soon as the first line is
complete. CodeMode continues receiving the remaining lines at the same time. Without
eager mode, neither call begins until the model has produced the whole snippet.
The code still counts as one run_code call. It uses one REPL session, one tool-call limit,
and one combined result. Hooks on fetch_item and other tools called by the code still run.
Hooks around run_code itself run only after the model has finished writing the call, so
they cannot approve or change lines that eager mode has already run.
Configured Monty resource limits still apply, but max_duration_secs and the sleep allowance
count per fragment: each eager fragment and the remaining code get their own, so an eager
call can run longer in total than the same code without eager mode. Memory is shared by the
session.
Keep these limitations in mind:
- Eager mode cannot undo side effects from code that has already run.
- With a parallel
InputGuardrail, a nested tool call from an eager statement waits for the guard’s verdict before it runs, so a blocked prompt runs no tool. - If the model later requests
restart: true, some work may run again. - If the model changes an earlier line while streaming,
CodeModeresets the REPL and asks the model to send the code again. - Eager mode trusts that the provider preserves the streamed
run_codepart and its tool name. If a provider removes or renames the part, the work that already ran cannot be undone. - Eager execution is used only when
run_codeis the first tool call in a model response. Later tool calls wait for normal dispatch so they run in the order the model requested. - Eager mode is disabled when using durable execution such as Temporal or DBOS.
- Eager mode needs asyncio, like the rest of the sandbox executor.
- If a statement is interrupted before it finishes, for example because the call failed validation, the session restarts and the next snippet must recreate its state.
- Nested tools called from eager statements must cooperate with asyncio cancellation. When
a run ends or a streamed call is invalidated,
CodeModecancels the in-flight work and waits a bounded time (currently 5 seconds) for it to release. Work that does not release in time is abandoned; it cannot start further tool calls. - Tools called from statements that ran early are traced before the
run_codespan opens.
speculate starts side-effect-free tool calls while the model is still writing the
run_code call. As the code argument streams in, CodeMode looks for calls to the named
tools whose arguments are all keyword literals. Each one starts once the line that completes
it has streamed, even if the statement around it (an if arm, a with body) is not finished
yet. When the completed snippet runs and reaches the same call, it takes the result that is
already in flight instead of starting the tool cold. This overlaps tool latency with
model generation (speculative programmatic tool calling,
https://alexzhang13.github.io/blog/2026/spec-ptc/).
A speculated call can run for a branch the snippet never takes. Read-only is necessary but not sufficient: reading changing state earlier can produce a different answer. Choose tools whose results and external interactions are acceptable at launch time, even if never used. Unused requests can still incur API charges, consume rate limits, and send arguments to an external service. Cancellation does not undo a request that has already been sent.
This example registers two independent lookups over fixed data. Running it requires provider
credentials, such as OPENAI_API_KEY. Real network lookups offer more opportunity to overlap
latency than these local functions.
from pydantic_ai import Agent
from pydantic_ai_harness import CodeMode


def lookup_author(*, title: str) -> str:
    """Find a book's author in a fixed catalog."""
    return {'Frankenstein': 'Mary Shelley'}.get(title, 'Unknown')


def lookup_year(*, title: str) -> int | None:
    """Find a book's publication year in a fixed catalog."""
    return {'Frankenstein': 1818}.get(title)


code_mode = CodeMode(speculate=['lookup_author', 'lookup_year'])
agent = Agent(
    'openai:gpt-6.1-sol',
    capabilities=[code_mode],
    tools=[lookup_author, lookup_year],
)
result = agent.run_sync(
    'Use run_code to look up the author and publication year of Frankenstein. '
    'Call both tools independently with the literal keyword argument title="Frankenstein".'
)
print(result.output)
print(code_mode.speculation_stats)
The model chooses the snippet, so the prompt does not guarantee speculative launches. Calls the snippet never claims are cancelled when the snippet finishes successfully. A snippet that fails before it runs (a syntax or type error) keeps its launches so the retry can claim them; whatever the retry leaves unclaimed is cancelled when the following model step starts.
Instead of naming tools, pass speculate='declared' to trust what the tools say about
themselves: tools marked Tool(..., metadata={'read_only': True}), and MCP tools whose
server publishes the readOnlyHint annotation. Idempotence is not enough, an idempotent
delete still deletes, so idempotent declarations do not count. A declaration is the tool
author’s claim, not a proof, so 'declared' extends the same trust to authors that an
explicit list places in you.
from pydantic_ai import Agent, Tool
from pydantic_ai_harness import CodeMode


def search(query: str) -> str:
    """Look something up."""
    return f'results for {query}'


agent = Agent(
    'openai:gpt-6.1-sol',
    capabilities=[CodeMode(speculate='declared')],
    tools=[Tool(search, metadata={'read_only': True})],
)
At snippet execution, Code Mode also scans for eligible literal calls not already in flight,
subject to the launch limit and ordering barriers. Those calls can overlap instead of waiting
for each await in turn. Eligible calls in both arms of an if/else can start; the taken
arm claims its result and the other launch is discarded.
Lookahead stops at a known tool call that is not eligible, including a sequential tool.
For example, if update_record is not eligible and search is eligible:
await update_record(key='status', value='ready')
await search(query='status')  # Runs after the update, not speculatively ahead of it.
Code can also reach a tool that is not eligible without naming it, for example through a
helper defined in an earlier snippet. A launch is not used if a call to a tool that is not
eligible, native or inside run_code, starts or finishes after the launch. The dispatch runs
the tool normally instead and counts as a miss; the launch is discarded as wasted work.
Only tool calls move this boundary: writes the sandbox makes through mount or os_access
do not, so do not make a tool eligible if it reads state those writes change.
To overlap an earlier blocking read with later calls, that read must also be eligible.
Streamed run_code parts following another model tool call wait for normal dispatch.
Eligibility is a trust decision, not an analysis of arbitrary Python side effects.
Keep these limitations in mind:
- Only calls with literal keyword arguments can start early. A call whose argument comes from an earlier statement waits for that statement.
- Calls are found in the streamed text, so a call spelled inside a string literal or a comment can start too. It is discarded when the snippet finishes.
sequentialtools never speculate, and nothing speculates when the run’s parallel execution mode issequential.- With a parallel
InputGuardrail, a speculated call waits for the guard’s verdict before it runs, so a blocked prompt runs none of them. - Hooks on a speculated tool run when it starts, not when the snippet claims it. Hooks,
approval, and guardrails on
run_codeitself run only after the model has finished writing the call, so they cannot stop a call that has already started early; this is the same contract as eager mode. - At most
max_tool_callscalls (and never more than 32) start early perrun_codecall; later ones run cold. This speculative allowance is separate from the snippet’s dispatch budget: unclaimed launches are extra work, not a reservation againstmax_tool_calls. - Under a
tool_calls_limit, a call counts toward the limit from the moment it starts early, including one the snippet never claims. A launch the limit refused runs cold if the snippet asks for it. - Speculated tools must cooperate with asyncio cancellation. Cleanup requests cancellation and waits up to five seconds per streamed call, then stops waiting. A tool that suppresses cancellation can outlive the run; this timeout does not forcibly stop its work.
- Enabling
speculateputs runs in streaming mode, and the option is disabled under durable execution such as Temporal or DBOS.
speculate composes with eager=True: eager execution runs the statements the model has
finished writing, and speculation starts the calls it has not reached yet (branch arms, calls
after a slow statement). Statements that eager mode runs claim those launches too.
CodeMode.speculation_stats counts launches across every run using that capability instance,
and its counters stay at zero when speculation is disabled. Take before/after snapshots for a
per-run comparison. Successful run_code returns can also carry a speculation entry in
history-only metadata, alongside tool_calls and tool_returns. Model-visible content is unchanged.
| Metric | Scope | Meaning |
|---|---|---|
launched | Capability instance | Calls started speculatively, during streaming or execution. |
adopted | Capability instance | Speculative outcomes consumed by actual dispatches, including tool errors. |
evicted | Capability instance | Unclaimed launches discarded or sent a cancellation request. |
hits | run_code return | Dispatches that consumed a speculative outcome. |
misses | run_code return | Dispatches to eligible tools that found no usable launch and ran normally. |
wasted | run_code return | Unclaimed launches discarded at this call’s successful completion. |
hidden_ms | run_code return | Sum of launch-to-settlement durations for adopted calls. |
hidden_ms is not measured end-to-end time saved: calls can overlap, and it includes time
spent waiting for a launch that was still running when claimed, or for a parallel
InputGuardrail verdict. Compare total run latency and external request cost with speculation
on and off. Neither evicted nor wasted proves that an unused call completed, stopped, or
avoided its cost.
The lifecycle is also emitted as
capability events in the code_mode
namespace, so UIs and other capabilities can follow it live from the run’s event stream:
SpeculativeCodeUpdateEvent (the decoded snippet so far, with its closed-statement
boundary), SpeculativeCallLaunchedEvent (with the launching statement’s line span and a
phase of streaming or execution), SpeculativeCallSettledEvent (only while the stream
is still flowing; a call that finishes later reports its state on its claimed or evicted
event instead), and, once the snippet runs, SpeculativeCallClaimedEvent,
SpeculativeCallMissedEvent, and SpeculativeCallEvictedEvent.
- Is the tool registered and exposed inside
run_code, rather than kept native? - Is its original tool name allowlisted, or does it carry a trusted read-only declaration?
- Does the generated call use literal keyword arguments rather than variables or positional arguments?
- Does an earlier non-eligible tool call block lookahead, or an earlier model tool call defer it?
- Is the tool marked
sequential, or is the run using global sequential execution? - Is durable execution active, or has the per-call speculative launch limit been reached?
If these checks pass, inspect the generated code and launch events. Oversized streamed arguments and exhausted parser-work budgets also stop stream scanning; speculation is an optimization, not a guarantee that every eligible call starts early.
Set monty_sandbox to a ws:// or wss:// URL to run sandboxed code on a remote Monty worker
instead of a local subprocess:
from pydantic_ai import Agent
from pydantic_ai_harness import CodeMode

agent = Agent(
    'anthropic:claude-sonnet-5-5',
    capabilities=[CodeMode(monty_sandbox='wss://sandbox.example.com/monty')],
)
A URL connects without a key. To send headers or set other pool options, pass a sync or async
function that returns a pydantic_monty.AsyncMontyWebsocket instead; Code Mode builds a pool from
it for each run. That pool’s request_timeout, 10 seconds by default, limits how long code runs
between tool calls, in place of max_duration_secs.
Use wss:// unless the server is on a network you trust: the connection carries your agent’s tool
calls and their results.
Only code execution moves to the worker. Your tools, mount directories, os_access, and print
output stay in your process, and REPL state persists across run_code calls as it does locally.
The run_code description lists the standard library modules Monty 1.4 can import, so run the
worker on pydantic-monty>=1.4.0.
Install both integrations:
pip install "pydantic-ai-harness[codemode,temporal]"
uv add "pydantic-ai-harness[codemode,temporal]"
Construct the named agent and its stable-ID toolsets outside the workflow, then attach
TemporalDurability alongside CodeMode:
from pydantic_ai import Agent
from pydantic_ai.durable_exec.temporal import TemporalDurability
from pydantic_ai_harness import CodeMode

agent = Agent(
    'openai:gpt-6.1-sol',
    name='coding-agent',
    capabilities=[CodeMode(), TemporalDurability()],
)
Follow the Pydantic AI Temporal guide to call the
plain agent from a workflow and register its activities with PydanticAIPlugin and either
__pydantic_ai_agents__ or AgentPlugin.
PydanticAIPlugin passes pydantic_monty through Temporal’s workflow sandbox. This makes Monty
runnable there, but run_code still executes in workflow code and is re-executed during replay.
This works with local workers and with monty_sandbox. With a remote worker, replay connects
to the worker again, so it must be reachable whenever the workflow replays.
Model requests and, by default, nested tool calls cross Temporal activity boundaries;
asyncio.gather can schedule nested tool activities concurrently. The REPL is process-local state
for one agent run, not durable storage. Replay reconstructs it by running the recorded snippets
again against recorded activity results.
Keep workflow-side code deterministic. mount reads and writes, os_access callbacks, and
host-clock calls happen again during replay; changing their results can change which activities the
workflow schedules and cause a NondeterminismError. Put external reads, writes, clock access, and
other side effects in wrapped tools so Temporal records them as activities. Replay may not flag
changed arguments when the same activity remains at the same history position, so replay validation
is not a substitute for this boundary. Temporal activity timeouts apply to nested tools, not pure
computation inside run_code. The workflow waits while the sandbox computes, and Temporal fails a
workflow task that does not yield within 2 seconds, so move heavier computation into a tool.
Clock, environment, and randomness calls reach os_access on the workflow’s own thread, so a
handler can answer datetime.now() with workflow.now() and stay replay-safe. File calls are
answered by Monty from the mounts first and reach the handler on another thread.
Nested tool calls inside run_code produce their own spans when instrumented with Logfire or any OpenTelemetry backend: each run_code span fans out into the tool calls the model issued from inside the sandbox. See the Pydantic AI Logfire docs for setup.
Suspension-limit retries use the existing run_code error span and nested tool spans, rather
than a separate capability span. The retry includes bounded started-call context and recovery
guidance. Monty has no typed exhaustion marker, so a tool error with identical wording receives
conditional guidance rather than a definitive exhaustion event.
The run_code tool return also carries metadata with every nested call, keyed by call id:
from pydantic_ai import Agent
from pydantic_ai.messages import ToolReturnPart
from pydantic_ai_harness import CodeMode

agent = Agent('anthropic:claude-sonnet-5-5', capabilities=[CodeMode()])


@agent.tool_plain
def get_weather(city: str) -> dict:
    """Get current weather for a city."""
    return {'city': city, 'temp_f': 72}


result = agent.run_sync("What's the weather in Paris?")

for msg in result.all_messages():
    for part in msg.parts:
        if isinstance(part, ToolReturnPart) and part.tool_kind == 'code_mode.run_code':
            metadata = part.metadata or {}
            tool_calls = metadata['tool_calls']    # dict[str, ToolCallPart]
            tool_returns = metadata['tool_returns']  # dict[str, ToolReturnPart]
The run_code tool declares the 'code_mode.run_code' tool kind, so its call parts are promoted to RunCodeCallPart (from pydantic_ai_harness.code_mode). A hook or history processor can recognize them with isinstance instead of matching the tool’s name, and read the submitted code from code (or all its arguments, validated as RunCodeArgs, from typed_args):
from dataclasses import dataclass, field
from typing import Any

from pydantic_ai import Agent, RunContext, ToolDefinition
from pydantic_ai.capabilities import AbstractCapability, ValidatedToolArgs, WrapToolExecuteHandler
from pydantic_ai.messages import ToolCallPart
from pydantic_ai_harness import CodeMode
from pydantic_ai_harness.code_mode import RunCodeCallPart


@dataclass
class RecordSnippets(AbstractCapability[Any]):
    snippets: list[str] = field(default_factory=list)

    async def wrap_tool_execute(
        self,
        ctx: RunContext[Any],
        *,
        call: ToolCallPart,
        tool_def: ToolDefinition,
        args: ValidatedToolArgs,
        handler: WrapToolExecuteHandler,
    ) -> Any:
        if isinstance(call, RunCodeCallPart) and call.code is not None:
            self.snippets.append(call.code)
        return await handler(args)


agent = Agent('anthropic:claude-sonnet-5-5', capabilities=[CodeMode(), RecordSnippets()])
run_code calls recorded before CodeMode declared this kind load as plain ToolCallParts. ToolCallPart.narrow_type(part, tool_kind='code_mode.run_code') promotes one.
A representative run wires CodeMode up against an MCP server and a web search and asks it to find the most-discussed Hacker News story across three feeds, pull the comment thread and the submitter’s profile, and search the web for follow-up coverage. CodeMode collapses that into two run_code calls: the first fetches all three feeds in parallel via asyncio.gather, dedupes by id, filters by score, and ranks by comment count — in plain Python; the second batches the three follow-up calls (hn_get_thread, hn_get_user, duckduckgo_search) together.
See the full Logfire trace -> Each run_code span fans out into the tool calls the model issued from inside the sandbox.
Sandboxed code starts with no access to the host’s files, environment, or clock. Two parameters add controlled filesystem, environment, or clock behavior.
Both parameters are fixed when the capability is built, so construct CodeMode per request to scope the configured access to that request.
Reach for mount when the agent works with real files: analyzing a dataset you’ve dropped in a folder and writing a report back, editing a checkout, or processing a batch of documents. Sandboxed pathlib code reads and writes under the mounted path. (For environment variables or the clock, use os_access instead.)
Mounts are directories on the machine running the agent, not the run’s workspace. With a remote sandbox such as ModalSandbox, Shell and FileSystem act in the sandbox while mounted pathlib code still reads and writes the host. Use the workspace tools for files the model shares with its commands.
from pydantic_ai import Agent
from pydantic_monty import MountDir
from pydantic_ai_harness import CodeMode

# The agent can read /work/data.csv and write /work/summary.md back to the host:
agent = Agent(
    'anthropic:claude-sonnet-5-5',
    capabilities=[CodeMode(mount=MountDir(virtual_path='/work', host_path='/tmp/agent-workspace', mode='read-write'))],
)
A MountDir defaults to copy-on-write mode='overlay': the sandbox reads host files and sees writes made during the current run_code call, but Monty discards those writes before the next call and they do not reach the host. Pass mode='read-write' when later calls need to read the writes, or mode='read-only' to forbid writes. mount also accepts a list of MountDir for multiple mount points.
Reach for os_access when the agent needs environment variables, the current date and time, or filesystem behavior you control. Hand it a ready-made OS implementation (AbstractOS), or a callback that decides each call — so you can inject just the secrets it needs, pin “now” for reproducible runs, or route file access to your own store.
from pydantic_ai import Agent
from pydantic_monty import OSAccess
from pydantic_ai_harness import CodeMode

# Give the agent a fixed set of environment values:
agent = Agent(
    'anthropic:claude-sonnet-5-5',
    capabilities=[CodeMode(os_access=OSAccess(environ={'API_BASE': 'https://api.example.com'}))],
)
A callback receives each OS call and decides its fate:
from pydantic_ai import Agent
from pydantic_monty import NOT_HANDLED
from pydantic_ai_harness import CodeMode

allowed_env = {'API_KEY': 'sk-...'}


def my_os(*, name, args, kwargs, **_):
    if name == 'os.getenv':
        # Answer the call: allow-listed keys resolve, every other key reads back
        # as None -- absent, exactly like a real unset variable.
        return allowed_env.get(args[0])
    # Refuse everything else: NOT_HANDLED makes the call fail in the sandbox.
    return NOT_HANDLED


agent = Agent('anthropic:claude-sonnet-5-5', capabilities=[CodeMode(os_access=my_os)])
The callback takes keyword arguments and may be async. The older positional form, my_os(name, args, kwargs),
still works but is deprecated and will be removed in the next breaking release.
Your callback’s return value decides the call’s fate:
- Return any value — including
None,'', or0— and that becomes the result the sandbox sees.os.getenvreturningNonelooks exactly like a normal unset variable, so the agent’s code keeps running. This is how you hide something: answer with an empty value. - Return
NOT_HANDLEDand the call is treated as unsupported: it raises inside the sandbox and the model gets a retry. This refuses a capability outright — use it to block, not to say “no value”. ReturningNOT_HANDLEDfor a key the agent reasonably expects will burn retries.
Code runs inside Monty, a sandboxed Python subset. Key restrictions:
- No third-party imports. Allowed stdlib modules:
sys,typing,asyncio,math,json,re,unicodedata,datetime,time,random,os,pathlib,collections,itertools,functools,dataclasses,copy,base64,binascii,bisect,csv,decimal,hashlib,os.path,tomllib(each must be imported before use). asyncio.gather(...)accepts positional awaitables but no keyword arguments. Other task creation and wait APIs are unavailable.- No clock or randomness by default:
datetime.datetime.now(),datetime.date.today(),time.time(), and unseededrandomfail. They become available when anos_accesshandler implements them (the built-inOSAccessdoes).time.sleepandasyncio.sleepreally wait, up to the allowance described under resource limits; inside a Temporal workflow a sleep is a durable timer. - No
import *. - Filesystem I/O needs an
os_accesshandler or amount;os.getenv/os.environneed anos_accesshandler. - Tools requiring approval or with deferred (
CallDeferred) execution are sandboxed like any other tool; without aHandleDeferredToolCalls(or equivalent) capability on the agent to resolve them inline, calling one fromrun_coderaises an error that surfaces to the model as a retry. - Tool results reach the sandbox in the JSON shape their generated stub declares, since the stub is derived from the tool’s JSON schema.
Decimal,UUIDanddatetimearrive as strings, and mapping keys are stringified, so adict[int, str]of{1: 'a'}arrives as{'1': 'a'}.bytesandbytearrayare the exception: Monty carries binary natively, so they cross unchanged even though the stub declaresstrfor them. - A tool without a return schema is still callable, but its generated signature shows
-> Any, so the model has to guess the result’s shape.CodeModenames such tools in oneCodeModeReturnSchemaWarning(aUserWarningsubclass) per run. Give a function tool a return annotation, or have your MCP server declare anoutputSchema; when the server is not yours, silence just this category withwarnings.filterwarnings('ignore', category=CodeModeReturnSchemaWarning).
CodeMode works with Pydantic AI’s agent spec feature for defining agents in YAML or JSON:
# agent.yaml
model: anthropic:claude-sonnet-5-5
capabilities:
  - CodeMode: {}
from pydantic_ai import Agent
from pydantic_ai_harness import CodeMode

agent = Agent.from_file('agent.yaml', custom_capability_types=[CodeMode])
result = agent.run_sync('...')
print(result.output)
Pass custom_capability_types so the spec loader knows how to instantiate CodeMode. Arguments can be passed in the YAML too:
capabilities:
  - CodeMode:
      tools: ['search', 'fetch']
      max_retries: 5
- Code mode: make your agents 2x faster and 2x cheaper on long tasks (Pydantic)
- Tool use via code (Anthropic)
- Code mode in production (Cloudflare)
- Pydantic AI capabilities
Bases: AbstractCapability[AgentDepsT]
Capability that exposes selected tools as callables inside a run_code sandbox.
By default (tools='all') every eligible regular tool the agent has is wrapped
behind a single run_code tool — the model writes Python that calls them as
functions instead of issuing tool calls directly. Framework control tools,
undiscovered deferred tools, native fallbacks, and other code-execution tools
remain native.
Pass a list of tool names or a callable predicate to tools to split the
toolset: matching tools become callables inside the sandbox, and the rest
stay visible to the model as normal tool calls.
from pydantic_ai import Agent
from pydantic_ai_harness import CodeMode

# Sandbox all tools
agent = Agent('openai:gpt-5', capabilities=[CodeMode()])

# Sandbox only specific tools
agent = Agent('openai:gpt-5', capabilities=[CodeMode(tools=['search', 'fetch'])])
By default, sandboxed code cannot touch the host — no filesystem, environment variables, or clock. Two parameters open it up:
mountshares specific host directories: reach for it when the agent reads or writes real files.os_accessroutes the sandbox’s OS calls to a handler you provide: reach for it when the agent needs environment variables, the clock, or filesystem behavior you control.
The built-in OSAccess has an isolated filesystem and environment but uses the
host clock by default; custom OS handlers can expose other host resources.
from pydantic_monty import MountDir

agent = Agent('openai:gpt-5', capabilities=[CodeMode(mount=MountDir(virtual_path='/work', host_path='/tmp/agent-work'))])
Which wrapped tools should be sandboxed inside run_code.
'all'(default): every eligible regular tool the agent has is sandboxed.Sequence[str]: only tools whose names are listed are sandboxed.- Callable
(ctx, tool_def) -> bool | Awaitable[bool]: tools where the callable returnsTrueare sandboxed; the rest stay as native tool calls.
Type: ToolSelector[AgentDepsT] Default: field(default='all')
Maximum number of retries for the run_code tool (syntax errors count as retries).
Type: int Default: 3
Maximum nested tool calls dispatched by one run_code invocation.
Budget is reserved before each call is scheduled, so a snippet cannot allocate host tasks beyond this many. Calls past the budget are refused at the sandbox call site.
Type: int Default: 100
Give sandboxed code environment variables, the clock, and file I/O through a handler you provide; unset, they are unavailable.
Pass an AbstractOS such as OSAccess, or a handler called with keyword arguments (see
pydantic_monty.OsHandler). A plain function is called from a Monty thread, not the event
loop’s thread, with the run’s contextvars set, so it must not touch asyncio objects; an async
handler is awaited on an event loop instead. Inside a Temporal workflow, clock, environment, and
randomness calls run on the workflow’s own thread, so the handler can use workflow.now().
The positional (name, args, kwargs) form is deprecated.
Type: CodeModeOS | None Default: None
Host directories to expose to sandboxed pathlib code; each mount’s mode controls whether writes reach the host.
Type: CodeModeMount | None Default: None
Sandbox execution limits.
None applies a 30-second execution and 256 MiB heap backstop. max_duration_secs is per
snippet: no single run_code snippet runs longer than it, and it is not a run-wide budget.
'unlimited' removes the time and memory caps, but Monty’s finite suspension budget still
applies. Set max_suspensions to bound cumulative host interactions across consecutive snippets.
Type: CodeModeResourceLimits | Literal[‘unlimited’] | None Default: None
Execute complete streamed statements before the run_code call finishes.
Needs asyncio, like the sandbox executor, and is inactive under durable execution. Side
effects cannot be rolled back and run before hooks on run_code see the completed call.
See the Code Mode guide for the execution and restart semantics.
Type: bool Default: False
Launch side-effect-free sandbox calls while the run_code arguments are still streaming.
Calls to eligible functions whose arguments are all keyword literals start as soon as their
text has streamed; when the completed snippet dispatches the same call, the in-flight result
is adopted instead of starting cold. Pass the names of tools that are safe to run early, or
'declared' to trust what the tools declare about themselves (Tool(metadata=\{'read_only': True\}) or the MCP readOnlyHint annotation). At most max_tool_calls (and never more than
32) calls start early per run_code call, and they do not reserve from max_tool_calls:
unclaimed launches are extra bounded work alongside the dispatches the snippet makes.
Composes with eager. Inactive under durable execution and when the run’s parallel
execution mode is sequential. See the Code Mode guide for the mechanics.
Type: Sequence[str] | Literal[‘declared’] | None Default: None
Where sandboxed code runs: a ws:// or wss:// URL, which connects without a key, or a sync or async function that returns a pydantic_monty.AsyncMontyWebsocket, called for each run. Unset, code runs locally.
A function’s pool limits how long code runs between tool calls with its own request_timeout
(10 seconds by default), in place of max_duration_secs. Tools, mounts, os_access, and print
output stay in your process.
Type: str | Callable[[], AsyncMontyWebsocket | Awaitable[AsyncMontyWebsocket]] | None Default: field(default=None, repr=False)
Deprecated: pass monty_sandbox=url instead.
Type: str | None Default: field(default=None, repr=False)
Keep the run_code REPL across agent runs in this store.
Unset, each agent run starts a fresh REPL. With a store, a run that calls run_code restores
the state the store returns and saves the REPL when it ends, so a conversation of several runs
keeps its variables, imports, and function definitions. After restart: true the run saves its
new REPL, or None when the restarted snippet failed before creating one. A state Monty cannot
load is dropped and the run starts fresh. Not used under durable execution. See the Code Mode
guide for an example.
Type: CodeModeReplStore[AgentDepsT] | None Default: None
Keep the run_code tool definition cache-stable as the sandboxed toolset grows. Default: True.
With dynamic_catalog=True:
run_code.descriptionkeeps only the static base prose (sandbox restrictions, return-value contract), so the tool-definitions block stays byte-stable across discoveries;- the “available functions” catalog (TypedDict definitions + signatures) goes into the agent’s
instructions as an
InstructionPartwith the idtoolset:code_mode:catalogandon_change='append', so a discovery appends the updated catalog to the message history instead of rewriting the instructions. Like other appending blocks, it’s sent right after the static instructions, ahead of dynamic instructions that rewrite the prefix, and on Anthropic, Bedrock and OpenRouter’s Anthropic routes it gets a cache point of its own, so new conversations reuse it; - deferred tools that
run_codewill take over stay off the wire until they’re found through the localsearch_toolstool or by loading their capability, and are callable only fromrun_codeafter that, so no tool declaration changes. When atoolsselector keeps other deferred tools native,search_toolssearches those too and the native tool search isn’t sent. With the'bm25'and'regex'ToolSearchstrategies only the native tool search can find them, so they’re declared for it and the declaration is dropped once they move intorun_code; - the functions
run_codegains from tools a search found are announced in a shortSystemPromptPartenqueued throughRunContext.enqueue, naming them asrun_codecalls them. Loading a capability appends only the catalog update.
The cache stays intact only if a callable tools selector gives the same answer for a tool before and
after it’s revealed: one that sandboxes a tool only once it’s revealed declares it natively first and then
drops the declaration.
With dynamic_catalog=False, the signatures of all sandboxed tools are rendered into run_code’s
description instead, which lives in the prompt-cache-keyed tool-definitions block, so a tool revealed
mid-run (by ToolSearch or a capability load) changes the
description and invalidates the cached prefix from that point on. Deferred tools are declared to the
provider’s native tool search where there is one.
Earlier releases defaulted to False.
Type: bool Default: True
Aggregate launch/adopt/evict counters across this instance’s runs, when speculate is set.
Type: SpeculationStats Default: field(default_factory=SpeculationStats, init=False, repr=False)
Report the stream hook only when a streamed execution tier is enabled.
The base class detects a class-level override, which would put every CodeMode user in
streaming mode; gating on the instance keeps plain CodeMode runs non-streaming.
Type: bool
@classmethod
def from_spec(
    cls,
    tools: Literal['all'] | Sequence[str] | dict[str, Any] = 'all',
    max_retries: int = 3,
    *,
    id: str | None = None,
    description: str | None = None,
    defer_loading: bool = False,
    max_tool_calls: int = 100,
    resource_limits: CodeModeResourceLimits | Literal['unlimited'] | None = None,
    eager: bool = False,
    speculate: Sequence[str] | Literal['declared'] | None = None,
    monty_sandbox: str | None = None,
    dynamic_catalog: bool = True,
    **kwargs: Any,
) -> CodeMode[Any]
Build from an agent spec, naming the fields a spec can express.
Core reads this signature to generate the spec’s JSON schema. Inherited, core falls back
to the variadic base from_spec, because __init__’s AsyncMontyWebsocket hint is a
TYPE_CHECKING import, and publishes only the bare 'CodeMode'. Reading __init__
would not help: os_access, mount, repl_store, and a monty_sandbox factory have
no JSON schema, and would drop the keyword form.
**kwargs reaches __init__ unchanged, so a spec that set anything else still loads.
CodeMode[Any]
def get_ordering() -> CapabilityOrdering
CodeMode wraps around ToolSearch so that search_tools stays native.
CapabilityOrdering
@async
def for_run(ctx: RunContext[AgentDepsT]) -> CodeMode[AgentDepsT]
Return a fresh instance so concurrent runs don’t share announcement or speculation state.
CodeMode[AgentDepsT]
@async
def before_model_request(
    ctx: RunContext[AgentDepsT],
    request_context: ModelRequestContext,
) -> ModelRequestContext
Clear announcements that the next model step has incorporated or discarded.
def get_wrapper_toolset(
    toolset: AbstractToolset[AgentDepsT],
) -> AbstractToolset[AgentDepsT] | None
Wrap the agent’s assembled toolset, splitting it into native + sandboxed subsets if needed.
AbstractToolset[AgentDepsT] | None
@async
def wrap_run_event_stream(
    ctx: RunContext[AgentDepsT],
    *,
    stream: AsyncIterable[AgentStreamEvent],
) -> AsyncIterable[AgentStreamEvent]
Feed streamed run_code argument deltas to the eager pump and the speculation launcher.
Wrapped events pass through unmodified; the watchers act by side effect, enqueueing closed statements for the live REPL and launching eligible calls. Inactive under durable execution, where overlapping non-deterministic work with the stream has no place in a replayed workflow.
AsyncIterable[AgentStreamEvent]
@async
def after_tool_execute(
    ctx: RunContext[AgentDepsT],
    *,
    call: ToolCallPart,
    tool_def: ToolDefinition,
    args: ValidatedToolArgs,
    result: Any,
) -> Any
Announce newly-discovered tools from a local search_tools return.
Only active with dynamic_catalog=True. The native-search path is handled by
after_model_request instead
(server-side search emits a NativeToolSearchReturnPart rather than a regular tool
execute result).
@async
def after_model_request(
    ctx: RunContext[AgentDepsT],
    *,
    request_context: ModelRequestContext,
    response: ModelResponse,
) -> ModelResponse
Announce newly-discovered tools from a native (server-side) tool-search return.
Only active with dynamic_catalog=True.
Bases: Protocol[AgentDepsT]
Where CodeMode keeps the run_code REPL between agent runs.
Each agent run starts its own REPL. With a store, a run that calls run_code first loads the
state saved for it, and saves the REPL again when the run ends, so variables, imports, and
function definitions carry over to the next run. Key the state by what identifies the
conversation, usually ctx.conversation_id.
The state is opaque: Monty’s dump of the REPL, behind a header recording the resource_limits
it was saved under, since a restored REPL keeps the limits of the session it came from. A state
saved under other limits is dropped and the run starts fresh. Its size grows with the values the
REPL holds; a store that limits it can drop an oversized state and forget the old one.
Monty does not authenticate a dump, so return only states this application saved, from storage no one else can write to.
A store error does not fail the run: a failed load starts a fresh REPL, and a failed save
leaves what the store held before. A run whose load failed does not save, so the state it
could not read is still there for the next run, unless it restarted the REPL with restart: true.
A save still running after SAVE_TIMEOUT_SECONDS is cancelled; work it handed to a thread may
still finish, so write atomically. Each is logged as a warning.
@async
def load(ctx: RunContext[AgentDepsT]) -> bytes | None
Return the state saved for this run, or None to start a fresh REPL.
@async
def save(ctx: RunContext[AgentDepsT], state: bytes | None) -> None
Keep state for the next run; None means restart: true cleared the REPL, so forget it.