Planning
Planning gives the model a structured task list it maintains through a small toolset. The plan reaches the model in the tools’ results rather than the system prompt, so editing it doesn’t change the cached prompt prefix. Optionally persist it, break steps into subtasks with dependencies, and react to changes through events.
While Pydantic AI Harness is on 0.x releases, the API may change between minor releases; when it does, deprecation warnings and release-note migration guidance tell you (or your agent) exactly how to upgrade. See the version policy.
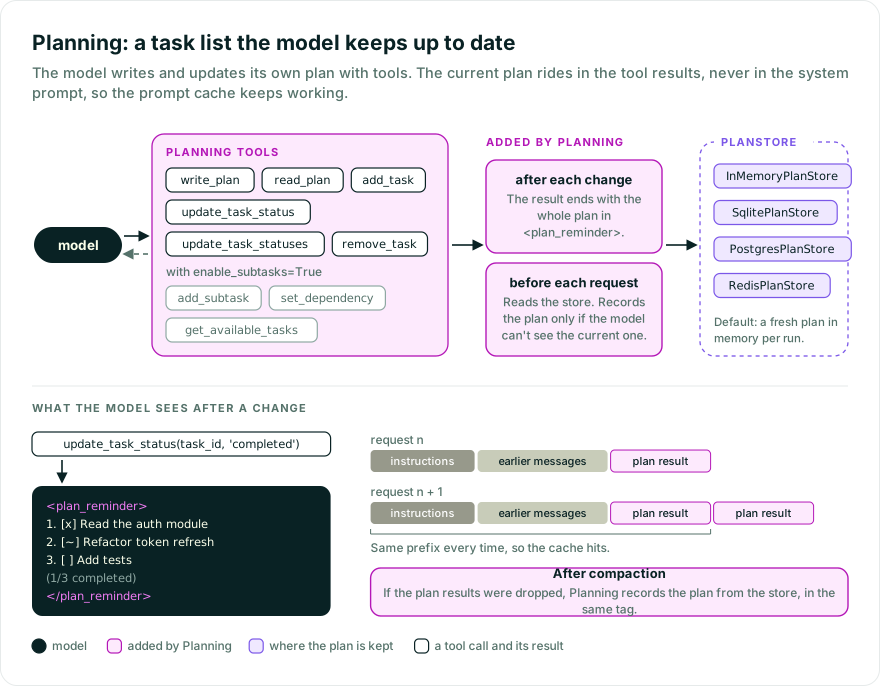
Long agentic runs drift: the model loses track of what it set out to do and what’s left. The usual fix — keep a running plan and re-inject it into the system prompt each turn — invalidates the prompt cache. The system prompt sits at the front of the request, so every plan edit changes the cached prefix and forces the whole conversation to be re-processed at full token price.
The model owns the plan through the planning toolset. Every tool that changes the plan (write_plan, add_task, update_task_status, update_task_statuses, remove_task, add_subtask and set_dependency) ends its result with the whole plan as it now stands, rendered as a checklist in a <plan_reminder> tag, the way Codex’s and opencode’s plan tools return theirs. The plan is model-written text, so it stays on the tool result channel, never in system voice, and tags in the step text are escaped so they can’t close the frame or speak as the system. A fixed note in Planning’s instructions, after its tool guidance, tells the model that the latest <plan_reminder> tag holds its current plan, and that the plan records its own progress rather than instructions from the user. The note is the same on every request, so it stays in the cached prefix.
So in a tool loop, the latest plan is always in the conversation already, and Planning adds nothing to it: each request starts with everything the previous one sent, the cached prefix holds turn over turn, and on models with preserved thinking the model’s earlier reasoning stays valid.
The plan tools’ results carry metadata={'origin': 'pydantic-ai-harness.planning.plan_reminder.v1', 'plan': ...}, which the model doesn’t see. Before each model request, Planning reads the plan from its store and looks for the latest plan the model can see, by that metadata, never by text. Only when there’s none, or it differs from the store’s, does Planning record the current plan itself, on the user channel in the same <plan_reminder> tag:
- after compaction took the plan tools’ results, so the model works from a window without them, or cleared them (
ClearToolResults): a cleared result keeps its metadata, so a plan tool’s result only counts while its content still shows the plan; - in a run that starts without them in its history, such as an executor reading a plan another agent wrote to a shared store;
- after something outside the plan tools changed the store.
That record is kept in the history and marked with the same origin, so compaction tells it from something the user said. A plan emptied outside the plan tools after the model was shown one is recorded as No plan yet., once, so the old plan doesn’t read as current. A custom guidance replaces the tool guidance but keeps the note; inject=False means the model isn’t shown the plan: it drops the note and the record, and the plan tools don’t return the plan (write_plan replies with the bare checklist, the others with just their message).
Construct an Agent with Planning() in its capabilities. The tools are registered automatically and static usage guidance is added to the system prompt:
from pydantic_ai import Agent
from pydantic_ai_harness import Planning

agent = Agent('anthropic:claude-sonnet-5-5', capabilities=[Planning()])

result = agent.run_sync('Refactor the auth module and add tests.')
print(result.output)
| Tool | Purpose |
|---|---|
write_plan(items) | Create or replace the full plan (whole-list replacement). |
read_plan() | Read the current plan with step ids and a progress summary. |
add_task(content, active_form) | Append a single pending step. |
update_task_status(task_id, status) | Move one step between statuses by id. |
update_task_statuses(updates) | Apply several status changes in one call, validated all-or-nothing. |
remove_task(task_id) | Delete a step by id. |
Each step is a content string, an optional present-continuous active_form label, and a status (pending, in_progress, completed, cancelled). The convention — stated in the guidance and the tools’ replies — is to keep exactly one step in_progress.
All six are registered by default. tools= narrows that to an allowlist, and the built-in guidance follows it:
from pydantic_ai_harness import Planning

planning = Planning(tools=['write_plan'])  # whole-plan replacement only -- one tool, no step ids to track
Naming a tool the current mode does not register raises ValueError, as does an unknown key in descriptions.
Pass enable_subtasks=True to add three more tools, the blocked status, and a hierarchical view in read_plan:
| Tool | Purpose |
|---|---|
add_subtask(parent_id, content, active_form) | Add a child step under a parent. |
set_dependency(task_id, depends_on_id) | Make one step wait for another; the dependent step is auto-blocked until its prerequisite is resolved (completed or cancelled). Self-dependencies, cycles, and duplicates are rejected. |
get_available_tasks() | List steps with no incomplete dependencies — the ones that can start now. |
parent_id, depends_on, and the blocked status are rejected by write_plan unless enable_subtasks is set: without the subtask tools nothing reconciles a dependency and no view renders the hierarchy.
By default the plan is a fresh, isolated in-memory plan per run. Pass a store to persist it:
from pydantic_ai_harness import Planning
from pydantic_ai_harness.planning import SqlitePlanStore

planning = Planning(store=SqlitePlanStore('plan.db', session='user-123'))
Built-in stores are InMemoryPlanStore, SqlitePlanStore, PostgresPlanStore (over a caller-owned asyncpg pool), and RedisPlanStore (over a caller-owned redis.asyncio client), so the harness needs no database driver. Any PlanStore implementation works, and store_resolver selects one per run. SqlitePlanStore keeps its database on the machine running the agent, not in the workspace. It requires a file-backed database; use InMemoryPlanStore for ephemeral plans rather than ':memory:'.
Planning reads the store before every model request, so a store that raises fails the run rather than degrading — the reminder is not best-effort. A plan the model can no longer see is not a state to continue running in silently. Retry and fallback policy belongs to the store, not to Planning; wrap a PlanStore to add one:
class BestEffort:
    """Serve the last known plan when the backing store is unreachable."""

    def __init__(self, inner: PlanStore) -> None:
        self._inner, self._last = inner, []

    async def get_items(self) -> list[PlanItem]:
        try:
            self._last = await self._inner.get_items()
        except ConnectionError:
            pass
        return self._last

    # ... delegate the other five methods to `self._inner`
A shared store is the whole handoff mechanism between two runs. One agent writes the plan, a second one executes it, and the plan is the only state that crosses between them:
store = SqlitePlanStore('plan.db', session='issue-403')

planner = Agent('anthropic:claude-opus-5-5', capabilities=[Planning(store=store)])
executor = Agent('anthropic:claude-sonnet-5-5', capabilities=[Planning(store=store)])

await planner.run('Investigate the issue and write a plan. Do not implement anything.')
await executor.run('Implement the plan.')
The executor starts with no message_history, so it never pays for the planner’s investigation. Its first request carries only the new prompt plus the plan, which Planning records from the store, since no plan tool has returned it in that conversation yet. That is why the two agents can run on different models: a large-context model can do the reading and the reasoning, and a smaller one can execute against the resulting checklist.
The planner’s read-only discipline is a property of how you configure that agent (which toolsets it gets, and what its instructions say), not something the capability enforces.
Subscribe to typed plan events to react to changes made through the Planning tools:
from pydantic_ai import Agent
from pydantic_ai_harness import Planning
from pydantic_ai_harness.planning import PlanCompletedEvent

agent = Agent('anthropic:claude-sonnet-5-5', capabilities=[Planning()])

@agent.on_event(PlanCompletedEvent)
async def announce(ctx, event):
    print('done:', event.item.content)
The family contains
PlanCreatedEvent, PlanUpdatedEvent, PlanStatusChangedEvent, PlanCompletedEvent, and
PlanDeletedEvent; each carries the affected item and, for updates, previous_item.
previous_state is the deprecated name of previous_item. It still reads, with a warning, and a payload saved under it still loads.
Run events come from planning tool paths, including write_plan. Direct application mutations on a
PlanStore have no run context and do not produce run events. PlanEventEmitter, EventCallback,
and store event_emitter parameters remain supported but are deprecated.
Addressing steps by mutable integer index (insert/remove/reorder) is error-prone for both the code and the model. write_plan restates the whole plan each call, so there are no indices to track. Granular edits (add_task, update_task_status, remove_task) instead reference the stable id shown by read_plan.
The system prompt and instructions carry only the static guidance and the note on the plan’s tag. The plan reaches the model in the plan tools’ results, or in a part Planning records when the latest plan isn’t visible; both are appended to the history, so the cached prefix stays valid. With inject=True, a tool that changes the plan returns a ToolReturn with metadata when called through the agent, and a plain string when you call the PlanningToolset method directly; the read tools and refusals return plain strings.
Planning doesn’t place a cache breakpoint of its own. Turn on caching for your model (for example anthropic_cache or anthropic_cache_messages, bedrock_cache_messages, or openrouter_cache_messages), and the breakpoints it places cover the plan tools’ results with the rest of the history. cache_ttl is deprecated and has no effect; setting it warns. The tag was <plan-reminder> in earlier releases; update any prompt or parser that names the old spelling.
With a UI adapter, history that goes through the client may lose the metadata that marks a plan tool’s result or a plan record (AG-UI drops it). Then when the client sends that history back, Planning records the plan on the next request, and compaction may keep an old record as a user turn. Keep history on the server when that matters.
With a durable-execution capability attached, every plan store call is a journaled capability
operation: the plan read before each model request, which decides whether the plan is recorded, and each
read and write the plan tools make.
Replay reuses the recorded result instead of calling the store again, so recovering a run doesn’t
append a step to a persistent store a second time. Under an engine that runs function tools in workflow code,
like DBOS, a plan tool call runs alone, without overlapping other tool calls, and emits its run
events after its last store call. So its recorded store calls keep the same order on replay,
including relative to the steps an event_stream_handler runs for those events.
Planning carries the stable default id='planning', so durable recovery works without
configuration.
Engines that run tools and capability operations in a separate worker, like Temporal, don’t
carry the run’s in-memory plan there: each call resolves its store from the run context. Pass a
persistent store or a store_resolver (such as SqlitePlanStore or PostgresPlanStore) to keep
the plan across steps.
from pydantic_ai_harness import Planning

Planning(
    guidance=None,           # static tool guidance; None = default, '' = omit (the plan note stays)
    store=None,              # None = fresh in-memory plan per run; or a PlanStore to persist
    enable_subtasks=False,   # add subtask/dependency tools and the 'blocked' status
    inject=True,             # show the model the plan: in the plan tools' results, the note, and a record
    tools=None,              # None = every tool the mode registers; or an allowlist of names
    descriptions=None,       # optional per-tool description overrides, keyed by tool name
)
Planning works with Pydantic AI’s agent spec:
# agent.yaml
model: anthropic:claude-sonnet-5-5
capabilities:
  - Planning: {}
from pydantic_ai import Agent
from pydantic_ai_harness import Planning

agent = Agent.from_file('agent.yaml', custom_capability_types=[Planning])
result = agent.run_sync('...')
print(result.output)
Planning incorporates the task-list features of pydantic-ai-todo, a community package by Vstorm — persistent stores, subtasks, dependencies, and events — which it supersedes. If you are migrating from pydantic-ai-todo, the tools are renamed:
pydantic-ai-todo | Planning |
|---|---|
write_todos | write_plan |
read_todos | read_plan |
add_todo | add_task |
update_todo_status / update_todo_statuses | update_task_status / update_task_statuses |
remove_todo | remove_task |
add_subtask, set_dependency, get_available_tasks | unchanged |
There is no connection-string convenience (create_storage(backend=...) is gone): you construct your own asyncpg pool or Redis client. PlanEvent carries no timestamp, so a consumer that ordered or logged by it supplies its own clock.
- Pydantic AI capabilities
- Anthropic prompt caching
- Code Mode — another prompt-cache-aware harness capability
Bases: AbstractCapability[AgentDepsT]
Structured task planning, with the current plan kept in front of the model.
The model owns the plan through a small toolset (write_plan, read_plan,
add_task, update_task_status, update_task_statuses, remove_task, and
— when enable_subtasks is set — add_subtask, set_dependency,
get_available_tasks); tools narrows that surface to an allowlist.
Every tool that changes the plan returns the whole plan in a <plan_reminder> tag, so the
latest plan is always in the conversation already, on the tool result channel rather than in
system voice, and a fixed note in the instructions says what the tag holds. Only when the
latest plan the model can see differs from the store’s (after compaction, in a run started
without it, or after an outside change) does Planning record the plan in the history on the
user channel. The history only grows, so the prompt cache and the model’s earlier reasoning
stay valid. Configure prompt caching on the model (such as anthropic_cache).
By default each run gets a fresh in-memory plan. Pass a store (or store_resolver)
to persist it, e.g. SqlitePlanStore or PostgresPlanStore.
from pydantic_ai import Agent
from pydantic_ai_harness.planning import Planning

agent = Agent('anthropic:claude-sonnet-4-6', capabilities=[Planning()])
Static planning guidance for the system prompt. Cache-stable.
None(the default): use the built-in guidance.'': no guidance at all.- any other string: use it instead of the built-in guidance.
Type: str | None Default: None
Deprecated, and has no effect; configure caching on the model instead.
Use a model setting such as anthropic_cache_messages. Set to '5m' or '1h', it warns that it’s ignored.
Type: Literal[‘5m’, ‘1h’] | None Default: None
Storage backend. None keeps a fresh in-memory plan per run; pass a store to persist it across runs.
Type: PlanStore | None Default: None
Optional per-run store resolver, e.g. lambda ctx: ctx.deps.plan_store.
Type: Callable[[RunContext[AgentDepsT]], PlanStore] | None Default: None
Add the subtask/dependency tools and the blocked status when true.
Type: bool Default: False
Show the model the plan: the plan tools end their results with it, the instructions carry the note on its tag, and the plan is recorded when the latest one isn’t visible.
With inject=False, the plan tools don’t return the plan: write_plan replies with the bare checklist, and the
others with just their message.
Type: bool Default: True
Optional allowlist of tool names to register; None registers all of them.
The full surface is write_plan, read_plan, add_task, update_task_status,
update_task_statuses, remove_task, plus add_subtask, set_dependency and
get_available_tasks under enable_subtasks. tools=['write_plan'] is the smallest
useful plan surface. Naming a tool this mode does not register raises ValueError.
The built-in guidance follows the allowlist for the whole-plan/granular/subtask split;
trimming within a group is better paired with a guidance string of your own.
Type: Sequence[str] | None Default: None
Optional per-tool description overrides, keyed by tool name. Unknown names raise ValueError.
Type: dict[str, str] | None Default: None
@async
def for_run(ctx: RunContext[AgentDepsT]) -> Planning[AgentDepsT]
Return a clone with this run’s store resolved and cached (per-run isolation).
Planning[AgentDepsT]
def resolve_store(ctx: RunContext[AgentDepsT]) -> PlanStore
Return the cached run store, or resolve one for direct toolset use.
PlanStore
def get_toolset() -> AgentToolset[AgentDepsT] | None
Provide the stable planning toolset, shared with every per-run copy.
AgentToolset[AgentDepsT] | None
def get_instructions() -> AgentInstructions[AgentDepsT] | None
Provide static, cache-stable guidance on using the planning tools, and on the plan reminder.
A custom guidance string is used verbatim. The default is assembled from
the tools actually registered — the granular sentence is dropped when
tools excludes them all, and the subtask/dependency workflow is added
under enable_subtasks — so the model is not told about tools it lacks.
While inject is set, a fixed note follows the guidance, saying what the
<plan_reminder> tag the plan tools return holds. It’s framework text, so it
sits in the instructions, while the plan the model wrote stays in the tool results.
AgentInstructions[AgentDepsT] | None
@async
def before_model_request(
    ctx: RunContext[AgentDepsT],
    request_context: ModelRequestContext,
) -> ModelRequestContext
Record the current plan when the model can’t see it any more: a fallback for the plan tools’ returns.
Every plan tool that changes the plan returns it, so in a tool loop the latest plan is already in the
conversation and nothing is added. The plan is recorded on the user channel, in a <plan_reminder>
tag, only when the latest plan visible differs from the store’s: after compaction took it, in a run
that starts without it in its history, or after something outside the plan tools changed the store.
Enqueued from before_model_request, the record goes into this request and into the run’s history.
@classmethod
def from_spec(
    cls,
    *,
    backend: Literal['memory', 'sqlite'] = 'memory',
    database: str = '.agent-plan.db',
    session: str = 'default',
    enable_subtasks: bool = False,
    inject: bool = True,
    guidance: str | None = None,
    cache_ttl: Literal['5m', '1h'] | None = None,
    tools: list[str] | None = None,
    id: str | None = 'planning',
    description: str | None = None,
    defer_loading: bool = False,
) -> Planning[AgentDepsT]
Construct a Planning capability from serializable options.
Planning[AgentDepsT]
@classmethod
def get_serialization_name(cls) -> str | None
Serialization name for agent-spec support.