Conversation Search
Give the model a search_conversation_history tool that BM25-ranks the history a StepPersistence capability already persists — earlier turns that compaction dropped from the live context, and past runs in the same conversation by default.
from pydantic_ai import Agent
from pydantic_ai_harness import ConversationSearch, SlidingWindowCompaction, StepPersistence
from pydantic_ai_harness.conversation_search import SnapshotHistorySource
from pydantic_ai_harness.step_persistence import SqliteStepStore

store = SqliteStepStore(database='sessions.db')
agent = Agent(
    'openai:gpt-6.1-sol',
    capabilities=[
        StepPersistence(store=store),
        ConversationSearch(SnapshotHistorySource(store), scope='conversation'),
        SlidingWindowCompaction(max_messages=40),
    ],
)


async def ask(question: str, conversation_id: str) -> str:
    result = await agent.run(question, conversation_id=conversation_id)
    return result.output
While Pydantic AI Harness is on 0.x releases, the API may change between minor releases; when it does, deprecation warnings and release-note migration guidance tell you (or your agent) exactly how to upgrade. See the version policy.
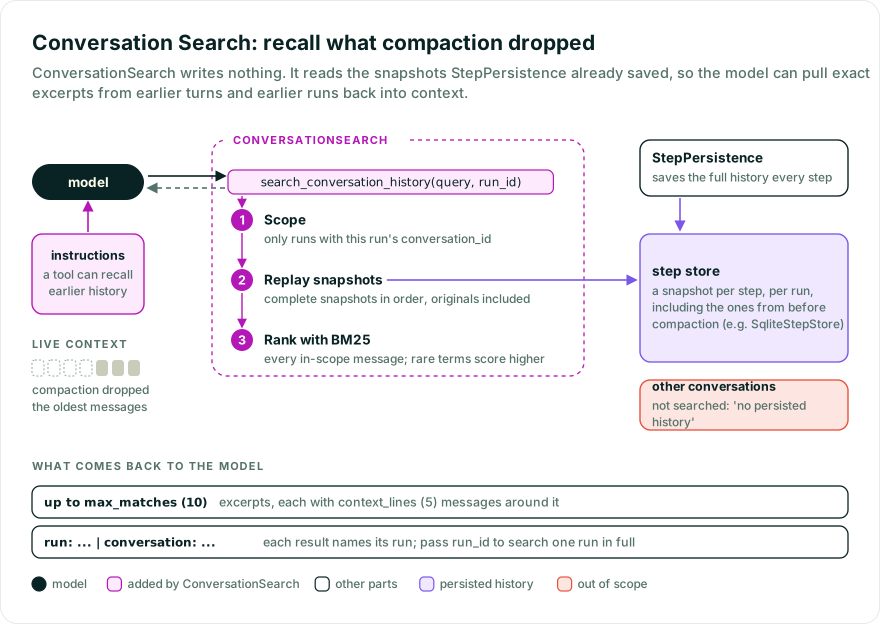
Compaction keeps the live history inside the context window, so an exact detail (a file path, a value, a decision) can end up only in a summary’s paraphrase, and nothing from earlier runs is in context at all. ConversationSearch writes nothing itself. It reads what StepPersistence stored, through a HistorySource, and lets the model pull exact excerpts back on demand. Give both capabilities the same store instance; they can be listed in any order.
- Ranking is BM25, implemented in pure Python with no extra dependencies. Rare terms score higher, and each word of a multi-word query is scored independently.
- Each result names its run (
run: ... | conversation: ...). The tool’s optionalrun_idargument searches one run’s full record, so a run a compaction receipt references is directly resolvable. - The tool reads the store when called, so it sees everything persisted so far, including earlier steps of the current run.
- History a run inherits through
message_historyis indexed under the run that first persisted it, so threaded runs do not return the same message once per run (with the instruction-change exception under Limitations). - Instruction changes recorded in history (
on_change='append') are searchable as system text; the initial instructions are not indexed. - Long messages are clipped to 500 characters for display (200 for system text and tool-call arguments). When the matched term lies past the cutoff, the excerpt shows the text around it instead of the start. The index always holds the full text.
StepPersistence saves the full history at every step. A compaction that persists its edits (like SummarizingCompaction) changes later snapshots only, so the earlier snapshots of the same run still hold the originals.
SnapshotHistorySource replays a run’s complete snapshots in order, drops summary artifacts, and appends only what each snapshot adds past its longest overlap with what it has collected so far. interrupted snapshots (unsettled tool work, synthesized tool returns) stay out. Overlap is matched on a content hash of each message, because durable executors (Temporal, DBOS) re-instantiate messages between steps. The hash leaves out what core adds to a message after it is first saved (timestamps, run ids, instruction changes appended by on_change='append'), and the later copy is kept.
HistorySource is the seam: a substrate that keeps an append-only entry log can implement it by replay and replace the snapshot adapter without touching the search layer.
scope='conversation' restricts the corpus to runs whose conversation_id matches the calling run’s. The tool description tells the model so, and the run_id argument cannot reach past it: an out-of-scope run gets the same “no persisted history” answer as one that does not exist.
A run’s conversation_id is the explicit conversation_id= argument, else the most recent one on message_history, else a fresh UUID7 (conversation_id='new' forces a fresh one). Threading message_history therefore keeps runs in one corpus, and a run with neither reaches only itself. A run whose RunContext has no conversation_id searches nothing and the tool says why, rather than pooling every unlabelled run in the store.
The value is trusted as given. UI adapters set it from client input (AG-UI’s thread ID, Vercel AI’s chat ID), so in a multi-tenant app derive it on the server from the authenticated user; see the threat model:
async def ask(question: str, user_id: str, chat_id: str) -> str:
    # Bind the conversation to the authenticated user, not a raw client-supplied id.
    result = await agent.run(question, conversation_id=f'{user_id}:{chat_id}')
    return result.output
Scoping applies to the RunRecords a HistorySource returns, so a custom source must populate conversation_id on them. scope='all' searches every run the source enumerates and returns verbatim excerpts from any of them; use it only when the store holds a single principal’s history.
scope used to default to 'all' and now defaults to 'conversation'. Leaving it unset emits one HarnessDeprecationWarning per instance; the warning will be removed in the next breaking release. Pass scope='all' to keep store-wide search or scope='conversation' to accept the new default. To silence every harness deprecation at once:
import warnings

from pydantic_ai_harness import HarnessDeprecationWarning

warnings.filterwarnings('ignore', category=HarnessDeprecationWarning)
| Option | Default | Purpose |
|---|---|---|
source | (required) | Where the corpus comes from. Use SnapshotHistorySource(store) over the store StepPersistence writes to. |
scope | 'conversation' (unset warns) | Restricts search to the calling run’s conversation_id. Use 'all' only for a store isolated to one principal. |
max_matches | 10 | Maximum matching excerpts the search tool returns. |
context_lines | 5 | Messages shown around each match (within the match’s run). |
bm25_k1 | 1.5 | BM25 term-frequency saturation. Lucene’s BM25Similarity uses 1.2. |
bm25_b | 0.75 | BM25 length normalization (Lucene default). |
add_instructions | True | Emit a short note telling the model the recall tool exists. |
tool_id | conversation-search | Toolset id for the search tool. |
ConversationSearch emits no spans of its own. Each search is a tool call, so core’s tool-execution span already records its duration, the query, and the result (content behind the usual instrumentation settings).
ConversationSearch declares the default id 'conversation_search'. The id keys the capability’s instructions, so they
can be addressed, and lets defer_loading=True work without one. Two ConversationSearchs on one agent that
share it are one search stated twice: they become one when they agree, and the agent raises a
UserError when it’s built if they differ. Merging them instead could widen the corpus one of them was given. The id is separate from tool_id, which names the toolset. To keep two, give each its own id and wrap them
in PrefixTools, since both register search_conversation_history.
Earlier releases declared no default id, so two always failed on the tool name when the run
started. Two identical ones now become one, and two that differ fail when the agent is built.
- Search only reaches what was persisted: history inherited from runs that never ran with
StepPersistence(for example a longmessage_historyfrom an unpersisted session) is lost if compaction drops it before the first snapshot. - Recovering compaction-dropped originals needs the pre-compaction snapshots. A store with bounded snapshot retention (a per-run snapshot cap) can prune them; the search then returns what the surviving snapshots carry.
- If a snapshot that dropped a prefix also repeats the exchange that ends the accumulated history, the repeat is absorbed into the overlap and indexed once.
- An inherited request that gets an instruction change in a later run is indexed again with that change, so its other parts can match twice. A run that branches from before such a change, followed by one that continues past it, indexes from the changed request onward once more.
- The tokenizer splits on word characters, so scripts written without spaces (Chinese, Japanese, Thai) match only a whole unbroken run, not a word inside it.
- The corpus is rebuilt on each call from every in-scope run’s snapshots, and every run record in the store is listed to apply the scope. A large store or history makes each search proportionally slower (#9361).
- Reading snapshots restores externalized media even though the index only names files; stores with remote media backends pay that fetch per search.
- Pydantic AI capabilities
- Step Persistence — the substrate this capability reads
- Compaction — the capabilities whose drops this one recovers from
Bases: AbstractCapability[AgentDepsT]
Search persisted conversation history with a dependency-free BM25 tool.
This capability persists nothing itself: it reads whatever history a persistence
capability already stores, through a HistorySource. Pair it with
StepPersistence sharing the same store, and the model can recall what
compaction dropped from the live context as well as anything from past runs in
the same conversation:
from pydantic_ai import Agent
from pydantic_ai_harness.compaction import SlidingWindowCompaction
from pydantic_ai_harness.conversation_search import ConversationSearch, SnapshotHistorySource
from pydantic_ai_harness.step_persistence import SqliteStepStore, StepPersistence

store = SqliteStepStore(database='sessions.db')
agent = Agent(
    'openai:gpt-5',
    capabilities=[
        StepPersistence(store=store),
        ConversationSearch(SnapshotHistorySource(store), scope='conversation'),
        SlidingWindowCompaction(max_messages=40),
    ],
)


async def ask(question: str, conversation_id: str) -> str:
    result = await agent.run(question, conversation_id=conversation_id)
    return result.output
Search is conversation-scoped by default (see scope), so reaching a past run
requires both runs to share a conversation_id. A run inherits the id from
message_history, so threading history through follow-up runs keeps them in one
conversation. History a run inherits is indexed under the run that first
persisted it, except a request a later run adds an instruction change to, which is
indexed again with that change.
StepPersistence snapshots each step boundary before the next compaction runs, so
the union of a run’s snapshots still holds messages a compaction later replaced.
The capabilities can be listed in any order: the tool reads the store when called.
Where the search corpus comes from. Use SnapshotHistorySource over the
store a StepPersistence capability writes to.
Type: HistorySource
How much of the store one search may reach.
conversation restricts the corpus to runs whose conversation_id matches the
calling run’s. A run with no conversation_id searches nothing and the tool says
so, rather than falling back to every other unlabelled run. all searches every
run the source enumerates and must only be used when the store is already isolated
to one principal.
None means the caller did not choose. It resolves to conversation and emits a
HarnessDeprecationWarning once per instance, because this default was all in
earlier releases and a store-wide caller would otherwise get a narrower corpus with no
error. Pass either value to silence it; neither is deprecated. The warning will be
removed in the next breaking release; the conversation-scoped default will remain.
Type: SearchScope | None Default: None
Toolset id for the search_conversation_history tool.
Type: str Default: 'conversation-search'
Maximum number of matching excerpts the search tool returns. Must be non-negative.
Type: int Default: 10
Number of surrounding messages shown around each search match, within the match’s run. Must be non-negative.
Type: int Default: 5
BM25 term-frequency saturation, non-negative. This capability’s default; Lucene’s
BM25Similarity uses 1.2.
Type: float Default: 1.5
BM25 length-normalization, between 0.0 and 1.0 (Lucene/Elasticsearch default).
Type: float Default: 0.75
Emit a short instruction telling the model the recall tool exists.
Type: bool Default: True
Stable capability ID, so its instructions are addressable and defer_loading=True needs none.
Separate from tool_id, which identifies the toolset. Two ConversationSearch sharing this id are one
search stated twice when they agree, and an error when they differ, since a merge could widen the corpus
one of them was given. To keep two, give each its own id and tool_id and wrap them in PrefixTools,
since their tool names are the same.
Type: str | None Default: 'conversation_search'
The scope actually applied: the caller’s choice, or conversation when unset.
Type: SearchScope
@classmethod
def combine(
    cls,
    capabilities: Sequence[AbstractCapability[AgentDepsT]],
) -> AbstractCapability[AgentDepsT]
Two under one id are one search stated twice; two that disagree raise rather than merge.
AbstractCapability[AgentDepsT]
def get_toolset() -> AgentToolset[AgentDepsT] | None
Provide the search_conversation_history tool over the source.
AgentToolset[AgentDepsT] | None
def get_instructions() -> AgentInstructions[AgentDepsT] | None
Tell the model the recall tool exists, unless add_instructions is false.
The wording follows scope so it never describes a corpus narrower than the
one configured.
AgentInstructions[AgentDepsT] | None