System Reminders
SystemReminders re-states targeted behavioral guidance partway through a run — on a fixed cadence or reactively from a condition — to counter the instruction fade that sets in over many turns, without moving the cached prompt prefix.
While Pydantic AI Harness is on 0.x releases, the API may change between minor releases; when it does, deprecation warnings and release-note migration guidance tell you (or your agent) exactly how to upgrade. See the version policy.
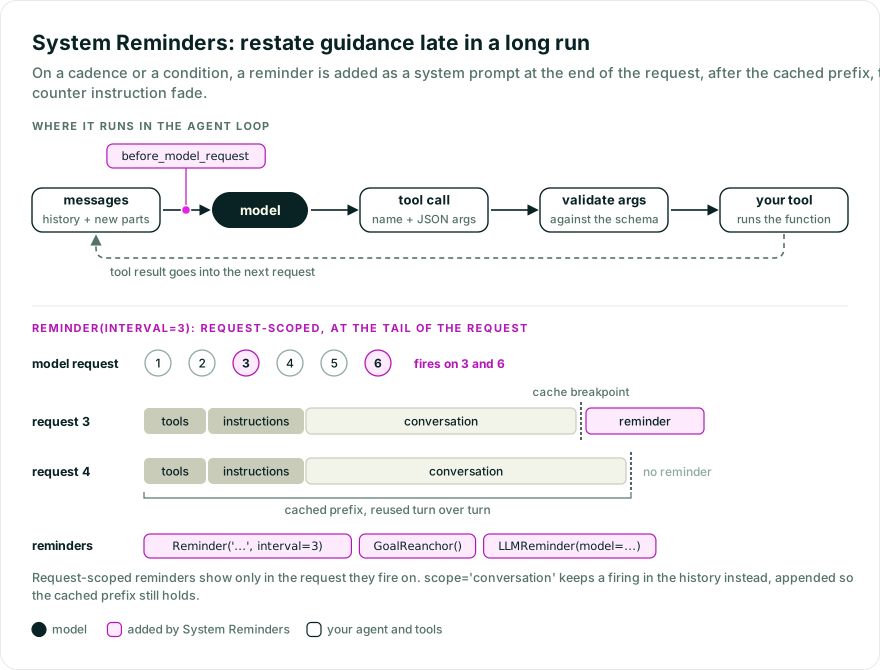
Long multi-turn runs suffer instruction fade: after many tool-use turns the model progressively ignores the guidance it was given at the start. A single start-of-session system prompt is not enough for extended work. The fix is to re-state targeted guidance mid-run — on a fixed cadence, or reactively when a condition is detected.
SystemReminders injects reminders on each model request, either statically (Reminder, on a cadence) or dynamically (a callable that reads the run context). Each firing enqueues a request-scoped system prompt at the tail of the request. The model sees a request-scoped prompt only in the model request it’s part of: the next request, even the next step of the same run, no longer shows it. It’s recorded in the message history like any other part. A static Reminder can be a lasting reminder instead, kept in front of the model for the rest of the conversation.
- On Anthropic models that take mid-conversation system messages, it’s sent as a turn-scoped system message (
clear_at): every copy stays on the wire, the API stops rendering each one once the next request arrives, and a cleared one costs no tokens. Leaving earlier reminders in place is what keeps the cached prefix and the model’s earlier reasoning valid; deleting one would invalidate every thinking block after it on models with preserved thinking. - Everywhere else, it’s sent with its own request only, at the end, rendered like any other mid-conversation system prompt, and left out of later ones.
- The cache breakpoints your model’s caching settings place (such as
anthropic_cache) go before the reminder, so the cached prefix (tools + system + real conversation) is reused turn over turn and only the small reminder falls outside it.
Injecting into the system prompt or instructions instead would sit at the front of the request, so every reminder would bust the cached prefix. This capability avoids that.
Construct an Agent with SystemReminders(...) in its capabilities:
from pydantic_ai import Agent
from pydantic_ai_harness import SystemReminders
from pydantic_ai_harness.system_reminders import Reminder

agent = Agent(
    'anthropic:claude-sonnet-5-5',
    capabilities=[
        SystemReminders(
            reminders=[Reminder('Stay focused on the original request.', interval=5, tag=None)],
        )
    ],
)

result = agent.run_sync('Refactor the auth module and add tests.')
print(result.output)
A Reminder fires on a cadence within a run:
| Field | Purpose |
|---|---|
content | The reminder text. |
interval | Fire every N model requests (interval=3 fires on the 3rd, 6th, …). |
first_after | Request number of the first fire, then every interval after. None = first multiple of interval (plain modulo). |
trigger | Predicate over RunContext. When set, fires only when it returns True and the cadence matches. |
max_fires | Cap the number of fires per run. None = no limit. |
tag | Also wrap the content in <tag>\ncontent\n</tag>. None sends the raw content. Left unset, it’s None and warns that the default changed. |
scope | 'request' (the default) shows each firing for its own request only; 'conversation' keeps it in front of the model for the rest of the conversation. See Lasting reminders. |
A request-scoped reminder, the default, adds recency; it doesn’t keep a rule in force. The model sees each firing only in the request it fires on, so with interval>1 it sees the reminder on the requests where it fires and not on the ones in between, and a trigger or max_fires narrows that further. Text the model must follow at every step belongs in the agent’s instructions, which every request sends. Guidance it must still act on several steps after a firing can be a lasting reminder.
A reminder is a system prompt, so the model is already shown it as one: as a native system message where the model supports it, and in a <system> tag otherwise. It needs no tag of its own, so pass tag=None. The default used to be 'system-reminder': a Reminder that leaves tag unset sends the raw content and warns, and tag='system-reminder' restores the old wrapping.
The tag wrapping applies only to static Reminder content. A str a dynamic callable returns (including GoalReanchor’s) is sent as written; an LLMReminder’s GeneratedReminder is quoted as data, as described under Dynamic reminders.
By default a reminder is request-scoped: the model sees it on the request it fires on, and not after. That’s what a nudge about the next step needs, and the history doesn’t fill up with copies the model keeps re-reading. Some guidance has to outlast that step, such as an obligation the model meets several tool calls later. Set scope='conversation' (named as in SystemPromptPart.scope) to record each firing as a lasting system prompt instead:
from pydantic_ai_harness import SystemReminders
from pydantic_ai_harness.system_reminders import Reminder

SystemReminders(
    reminders=[
        Reminder(
            'Run the tests and report any failures before you finish.',
            interval=10,
            tag=None,
            scope='conversation',
        )
    ],
)
Each firing adds a SystemPromptPart to the message history for good, and every later request sends all of them again. So the history grows by one part per firing: with interval=N, a run of R requests gains R // N copies, and with the default interval=1, one on every request. The copies are appended and never moved, so the cached prefix holds, and with caching turned on for your model each earlier copy is read from cache. Use interval and max_fires to bound the growth: max_fires=1 records the reminder once per run.
Choose the scope by what the text has to do:
- Text that holds on every step and never changes belongs in the agent’s instructions, not in a reminder: it’s sent once per request at the start, cached, and never adds to the history.
- Text that matters for the next step only, or carries a value that changes (a count, a time, a budget), stays request-scoped, so stale copies don’t pile up in the history.
- Text that must still apply several steps after it fires is a lasting reminder.
A lasting reminder is operator text, sent in system voice like any other reminder. It’s a system prompt, so SummarizingCompaction summarizes it as a system message, never as something the user said, and keep_user_messages never keeps it. Its origin metadata keeps compaction from taking it for a summary an earlier release stored as a system prompt. Copies that compaction summarized away are recorded again on the reminder’s next firing.
A dynamic reminder is any callable (RunContext) -> str | None (sync or async), evaluated on every model request. Return a string to inject, or None to skip. This is the general seam for conditions that need run state — token budget, post-compaction, mode switches — without hardcoded detectors:
from pydantic_ai_harness import SystemReminders

SystemReminders(
    dynamic_reminders=[
        lambda ctx: 'Wrap up soon.' if ctx.run_step > 20 else None,
    ],
)
Every reminder is sent as a system prompt, so the model reads it with the authority of your instructions. Static Reminder content and a str a dynamic callable returns are operator text, sent in system voice as written: return only text you wrote yourself. The built-in dynamic reminders never put text they didn’t write in system voice.
GoalReanchor doesn’t quote the user at all: it points the model back at the user’s first request, which is already in the conversation. LLMReminder returns a GeneratedReminder, a distinct type rather than a str, so string operations can’t turn the generated text into operator text; a wrapper that passes it through keeps it as data.
SystemReminders sends a GeneratedReminder as a fixed framework note in system voice, which ranks the reminder below your instructions and the user’s request, and the generated text on the user channel in a <generated_reminder model="..."> tag. The two are one record in the message history, kept and sent together on every later request and seen together by compaction and summaries, so in history kept on the server the generated text doesn’t reach the model without the note that says what it is. History that round-trips through a UI client is the one exception: see UI history. Both parts carry origin metadata, so the reminders recognize their own records.
Every opening and closing spelling of a framing tag inside the generated text, <system> and the reminder tags included, is escaped (<system>), so it can’t end its tag, open another or speak as the system. LLMReminder also quotes the transcript it sends the reminder model, in <summary>, <goal> and <message role="..."> elements, starting at the latest native compaction boundary.
GoalReanchor points the model back at the run’s first user request and asks it to check its next action advances it. After native compaction it points at the request as the compaction summary records it, when the request itself is no longer in what the model sees. No model call, no dependencies:
from pydantic_ai_harness import SystemReminders
from pydantic_ai_harness.system_reminders import GoalReanchor

SystemReminders(dynamic_reminders=[GoalReanchor()])
LLMReminder has a model summarize a compact transcript (original goal + recent activity) into a short stay-on-task nudge. It requires an explicit model — there is no default model id — and falls back to GoalReanchor text on any error, so a failed generation never blocks the run:
from pydantic_ai_harness import SystemReminders
from pydantic_ai_harness.system_reminders import LLMReminder

SystemReminders(dynamic_reminders=[LLMReminder(model='anthropic:claude-haiku-5-5', interval=10)])
LLMReminder generates every interval model requests: the 10th, 20th, 30th, … by default, the cadence TrajectoryJudge reviews a run on. Each firing issues one extra model call (its usage is threaded onto the parent run via ctx.usage, so it shows up in result.usage, and the generation run is filed under the parent’s conversation_id), and adds its note and generated text to the message history for good, sent again on every later request. So interval bounds both: a run of R requests makes R // interval extra calls and gains 2 * (R // interval) parts. A run shorter than interval requests gets no generated reminder, which is the point of the default: instruction fade sets in over long runs. Set interval lower for a tighter cadence, and add GoalReanchor alongside it for a free check on every request in between:
from pydantic_ai_harness import SystemReminders
from pydantic_ai_harness.system_reminders import GoalReanchor, LLMReminder

SystemReminders(dynamic_reminders=[GoalReanchor(), LLMReminder(model='anthropic:claude-haiku-5-5', interval=5)])
The nested call runs under the parent’s usage_limits with one request held back for the model request it precedes, so the reminder cannot push a run past its request_limit; once the budget is that tight the generation is skipped and GoalReanchor text is used instead. Every other generation failure is logged at warning level with its traceback under the pydantic_ai_harness.system_reminders logger namespace, once per run, so a misconfigured model (bad id, missing key) shows up in the logs once per run rather than on every model request, while the run carries on with the fallback text.
Under a durability engine, a LLMReminder listed directly in dynamic_reminders is a journaled
capability operation: replay restores the recorded reminder instead of repeating the model call,
and a generation error is recorded as the GoalReanchor fallback rather than inheriting the
engine’s retry policy, so a best-effort reminder cannot stall the run. SystemReminders carries the
stable default id='system_reminders', so durable recovery works without configuration.
Only a direct entry takes that route. Two shapes do not:
- A wrapper of your own that calls
LLMReminder(to gate it on a condition, say) calls it from orchestration context, where engines that forbid I/O can fail the call outright. Called that way, it still applies itsinterval, counted in run steps (ctx.run_step). - An
LLMRemindersubclass that overrides__call__runs that override directly, so it cannot be journaled either.
Without a durability engine, generation runs directly in all three cases, with the same fallback to
GoalReanchor on error.
Subscribe to ReminderFiredEvent to observe reminders after they are appended:
from pydantic_ai import Agent
from pydantic_ai_harness import SystemReminders
from pydantic_ai_harness.system_reminders import Reminder, ReminderFiredEvent

agent = Agent(
    'anthropic:claude-sonnet-5-5',
    capabilities=[SystemReminders(reminders=[Reminder('...', interval=5, tag=None)])],
)

@agent.on_event(ReminderFiredEvent)
async def record(ctx, event):
    print(event.text)
Migration: on_fire remains supported but is deprecated. Move its callback body to this
subscription.
Per-run state (the request counter and per-reminder fire counts) is isolated via for_run, so concurrent runs on the same agent never share fire state.
Reminders never go into the leading system prompt or instructions, and the history only ever grows by appending, so it stays eligible for a cache hit. Plain reminders, GoalReanchor included, are request-scoped system prompts at the tail of the request, and the only added cost is reading each one once. A Reminder(scope='conversation') firing stays in the history and is sent again on every later request, so each copy is read from cache when the prefix before it is cached. The records an LLMReminder adds to the history, which every later request sends again, are read from cache when the prefix before them is cached, and paid for in full when it isn’t, so keep LLMReminder’s interval as long as the run allows and turn on caching for your model.
SystemReminders doesn’t place a cache breakpoint of its own. Turn on caching for your model (for example anthropic_cache or anthropic_cache_messages, bedrock_cache_messages, or openrouter_cache_messages), and the breakpoint it places lands before the reminder.
- Planning shows the plan in its plan tools’ results, with a note on it in its instructions, and records it in the history only when it isn’t visible any more. Both compose in one agent, and neither places a cache breakpoint.
- Loop detection (detect-and-interrupt with a nudge that stays in history) is Detect Loops.
SystemRemindersis cadence/condition steering, request-scoped by default or lasting.
The reminder is only added when the last message in the request is a ModelRequest and at least one reminder fires, so a turn where nothing fires adds nothing to the request. Provider-resume turns (where the request tail is a suspended ModelResponse that is echoed back verbatim) are skipped and do not consume a cadence slot.
With a UI adapter in its default manage_system_prompt='server' mode, history that goes through the client doesn’t keep an LLMReminder record intact. The dump leaves out the record’s system note but keeps its generated text, and AG-UI also drops the metadata that marks the text as reminder data. When the client sends that history back, the generated reminder reads as plain user text, and compaction may keep it as a user turn. Plain reminders, GoalReanchor included, are request-scoped and left out of the dump altogether, so they’re unaffected. A Reminder(scope='conversation') is a lasting system prompt, which the dump leaves out in 'server' mode like any other system prompt: history the client sends back doesn’t have its copies, so keep the history on the server for lasting reminders too.
If you use LLMReminder with a UI adapter, keep the message history on the server and don’t rely on the client’s copy. A durable fix is planned with CapabilityPart (#11029), and a server-held history mode for UI adapters is proposed in #11031.
SystemReminders.get_serialization_name() returns None: reminders take arbitrary callables, which cannot be serialized to an agent spec.
- Pydantic AI capabilities
- Request-scoped system prompts — the core primitive the reminders are built on
- Anthropic prompt caching
- Planning — another prompt-cache-aware harness capability
Bases: AbstractCapability[AgentDepsT]
Inject periodic or conditional reminders to counter instruction fade in long sessions.
Long multi-turn runs suffer instruction fade: after many tool-use turns the model
progressively ignores start-of-session guidance. SystemReminders re-injects targeted
guidance mid-run, either on a fixed cadence (Reminder) or reactively from a callable
(dynamic_reminders).
Each firing enqueues a request-scoped system
prompt at the end of the request: the model sees it for that request only, and it stays in the
message history, so the cached prefix and the model’s earlier reasoning stay valid. On Anthropic
models that support it, it’s sent as a turn-scoped clear_at system message that costs nothing
once its request has been answered; elsewhere it’s sent with its own request only. The cache
breakpoints the model’s caching settings place go before it. A Reminder(scope='conversation')
is recorded as a lasting system prompt instead, sent again on every later request.
from pydantic_ai import Agent
from pydantic_ai_harness.system_reminders import SystemReminders, Reminder

agent = Agent(
    'anthropic:claude-sonnet-4-6',
    capabilities=[
        SystemReminders(
            reminders=[Reminder('Stay focused on the original request.', interval=5, tag=None)],
        )
    ],
)
Static reminders injected on a cadence.
Type: Sequence[Reminder[AgentDepsT]] Default: ()
Callables evaluated every model request; return text to inject or None to skip.
Type: Sequence[DynamicReminder[AgentDepsT] | AsyncDynamicReminder[AgentDepsT]] Default: ()
Deprecated, and has no effect; configure caching on the model instead.
Reminders used to bring a cache breakpoint of their own, with a '5m' TTL by default. They’re
system prompts at the tail of the request now, and the breakpoints the model’s caching settings place (such as
anthropic_cache) land before them. Set to '5m' or '1h', it warns that it’s ignored.
Type: Literal[‘5m’, ‘1h’] | None Default: None
Deprecated callback invoked with each rendered reminder. Subscribe to ReminderFiredEvent instead.
Type: Callable[[str], None] | None Default: None
@async
def for_run(ctx: RunContext[AgentDepsT]) -> SystemReminders[AgentDepsT]
Return a fresh per-run instance with reset counters (config preserved).
The clone resets _request_count and _fire_counts, so concurrent runs on the
same agent do not share fire state.
SystemReminders[AgentDepsT]
@async
def before_model_request(
    ctx: RunContext[AgentDepsT],
    request_context: ModelRequestContext,
) -> ModelRequestContext
Enqueue the reminders that fire on this request as system prompts of their scope.
Enqueued from before_model_request, the prompts go into this request and into the run’s
history, as a ModelRequest of its own that’s sent merged into the request it follows.
@classmethod
def get_serialization_name(cls) -> str | None
Not spec-serializable: reminders take arbitrary callables.
Bases: Generic[AgentDepsT]
A static reminder injected on a cadence during an agent run.
The reminder text.
Type: str
Fire every N model requests within a run. interval=3 fires on the 3rd, 6th, 9th, … request.
Type: int Default: 1
Request number of the first fire. None (the default) fires on the first multiple of
interval (plain modulo). When set, the reminder fires at first_after, then every
interval requests after that.
Type: int | None Default: None
Optional predicate over the current RunContext. When set, the reminder fires only when
the trigger returns True and the cadence condition is met.
Type: Callable[[RunContext[AgentDepsT]], bool] | None Default: None
Maximum number of times this reminder may fire within a run. None means no limit.
Type: int | None Default: None
When set, wrap the content in an XML tag: <tag>\ncontent\n</tag>.
The default is None, which sends the raw content. That’s what a reminder needs: it’s already a
system prompt, which the model is shown as one, natively where the model supports it and in a
<system> tag otherwise. Leaving tag unset behaves exactly like tag=None, but warns that the
default used to be 'system-reminder'; pass tag=None to silence it. (The unset default is a
private sentinel shown as None, so the field’s type stays str | None.)
Type: str | None Default: _UNSET
How long each firing stays in front of the model.
Named as in SystemPromptPart.scope, which it sets.
'request' (the default) shows it for the request it fires on only. 'conversation' records each firing as a
lasting system prompt, sent again on every later request, so the history gains one part per firing: with
interval=N, a run of R requests gains R // N. Use it for guidance that must still hold after the step it
fires on, such as “run the tests before you finish”. Text that holds on every step belongs in the agent’s
instructions.
Type: Literal[‘conversation’, ‘request’] Default: 'request'
Bases: Generic[AgentDepsT]
Zero-cost dynamic reminder that points the model back at the run’s first user request.
No model call and no dependencies: it asks the model to check its next action advances the
user’s first request, which is already in the conversation, so it never repeats the user’s text
in system voice. Falls back to a static line when there is no user message yet. Add it to
SystemReminders.dynamic_reminders.
Bases: Generic[AgentDepsT]
Dynamic reminder whose text a model generates from a compact transcript.
On any error it falls back to GoalReanchor text, so a failed generation doesn’t block
the run. Add it to SystemReminders.dynamic_reminders.
It generates every interval model requests (the 10th, 20th, … by default), and each
firing adds a lasting record of two parts to the message history, so interval bounds both
the extra model calls and how fast the history grows. Its usage is threaded onto the parent
run (ctx.usage) and it runs under the parent’s usage_limits minus one reserved request, so
the reminder cannot push a run past its request_limit. Once the budget is that tight the
generation is skipped and GoalReanchor text is used instead.
When owned by SystemReminders, generation is a journaled capability operation under a
durability engine. Replay restores the generated text instead of repeating the model call.
Generate every N model requests within a run: the default 10 fires on the 10th, 20th, 30th, … request.
Each firing makes one extra model call and adds a framework note and the generated text to the message
history for good, so a run of R requests gains 2 * (R // interval) parts. interval=1 generates on every
request, the behavior before the default changed. Leaving it unset behaves exactly like interval=10, but
warns that the default used to be 1; pass interval=10 to silence it.
Type: int Default: _UNSET_INTERVAL
Reminder text a model generated, which SystemReminders never sends in system voice.
LLMReminder returns one. SystemReminders sends it as a lasting record of two parts: a fixed framework
note in system voice, and text quoted on the user channel in a <generated_reminder> tag. A plain
str a dynamic reminder returns is operator text, sent in system voice as written, so this is a
distinct type rather than a str: string operations can’t drop its provenance and promote it.
The text the reminder model generated, as it wrote it.
Type: str
The name of the model that generated it.
Type: str
The framework’s note, sent in system voice.
Type: str
text quoted in a <generated_reminder> tag, sent on the user channel.
Type: str