Memory
Give an agent a persistent notebook that it can update, search, and reuse across runs without loading every stored file into every prompt.
While Pydantic AI Harness is on 0.x releases, the API may change between minor releases; when it does, deprecation warnings and release-note migration guidance tell you (or your agent) exactly how to upgrade. See the version policy.
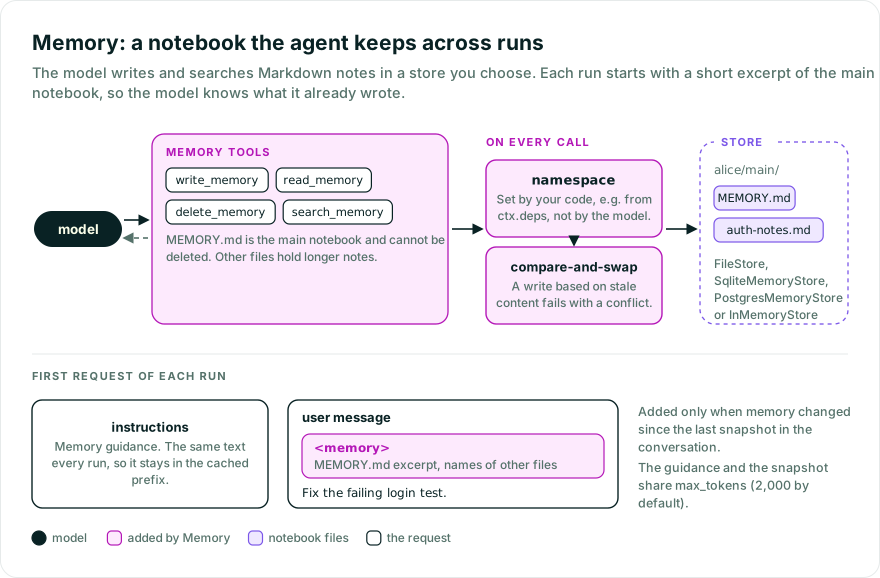
Memory gives each agent a notebook made of Markdown files:
MEMORY.mdis the main notebook. By default, a bounded excerpt and the names of other files are recorded with the user’s prompt as delimited user-role context, once per run in which they changed.- Other files hold longer or focused notes. The model reads them on demand or finds them with bounded text search.
The model gets four tools:
| Tool | Purpose |
|---|---|
write_memory | Append to a file or replace one unique text fragment. Writes use optimistic concurrency and an idempotency identifier derived from the run, its step, and the tool call. |
read_memory | Read a bounded prefix of one memory file. Left out when FileSystem can read the files (Reading memory with FileSystem). |
delete_memory | Delete a file. The main notebook is protected. |
search_memory | Search across notebook files, subject to configured result, character, and file-scan limits. |
from pydantic_ai import Agent
from pydantic_ai.capabilities import LocalWorkspace
from pydantic_ai_harness import Memory
from pydantic_ai_harness.memory import FileStore

agent = Agent(
    'anthropic:claude-opus-5-5',
    capabilities=[LocalWorkspace('.'), Memory(FileStore('.agent-memory'))],
    defer_model_check=True,
)
FileStore keeps the notes as Markdown files in the run’s workspace, so the model can also open them with its file tools. A run without a workspace fails at its start. With a read-only run workspace, the write and delete tools are hidden; a store with its own workspace follows that workspace’s permissions instead. Workspace refusals during mutations become tool failures. To keep them on your machine while the agent works in a sandbox, pass a backend: FileStore('.', workspace=LocalWorkspaceBackend('/var/lib/myapp/memory')).
The namespace is resolved by application code, not supplied to the tools. The model therefore cannot select another user’s namespace in a tool call.
When the store is a FileStore that keeps its files in the run’s workspace (no workspace= of its own, and a relative directory inside the working directory) and FileSystem is on the agent, read_memory steps aside for FileSystem’s read_file. The tool is marked with unless_tool_kind set to READ_FILE_KIND, so it is left out of every run step that has a tool of that kind. With a store_resolver, the store it returns for the run decides. The guidance in the instructions doesn’t name a reader, so it is the same in every run and stays in the cached prefix. An instruction block of its own, named directory, says where this scope’s files are, for example “Memory files are in .agent-memory/main/ in the workspace; read them with the file-reading tool.”, so the model knows even in a run that records no snapshot. The block is there from the first request, empty while no file reader is on the run, and appended to the history when one joins. Its text counts against max_tokens with the guidance and the snapshot: when it doesn’t fit, read_memory stays and the block says nothing; the injected <memory> block says so too, and the notices that pointed at read_memory (lines left out of the injected notebook, an old_text that was not found) name a read_file call on the file’s path instead.
InMemoryStore, SqliteMemoryStore, PostgresMemoryStore and a FileStore with a workspace= of its own keep their files where FileSystem cannot see them, so with those read_memory stays. With inject_memory=False, or when the guidance alone fills max_tokens so no snapshot fits, read_memory stays too: the injected <memory> block is where the model learns the files’ directory.
The decision is made from the store, not from FileSystem’s access rules. A FileSystem whose denied_patterns cover the memory directory, or whose allowed_patterns leave it out, still replaces read_memory but cannot open the files. Give the store a workspace= of its own to keep read_memory in that setup.
The directory includes the namespace. With file tools over the run’s workspace, the model can read every namespace’s files under directory, whether or not read_memory is offered, so give the store a workspace= of its own when namespaces separate users who must not see each other’s memory.
Automatic injection is on by default. The usage guidance goes in the model instructions, and stored memory goes in a <memory> block, a user-role part recorded with the user’s prompt. The guidance, MEMORY.md, and the list of other files share max_tokens (default 2,000, estimated at four characters per token); the default guidance alone uses about 200 of them. max_lines also caps the MEMORY.md lines shown, and max_memory_size caps each backend read. The file listing is bounded by the same budget, so the capability never requests an unbounded file or listing. Whatever does not fit is left out, with a note pointing the model to read_memory (or read_file, where it replaces read_memory) or search_memory. When the guidance alone fills the budget, nothing is injected and the memory.inject span records memory.outcome='budget_exhausted'.
When heading is set, the same ## {heading} labels both the trusted guidance and the user-role memory block.
from pydantic_ai_harness import Memory
from pydantic_ai_harness.memory import FileStore

memory = Memory(
    FileStore('.agent-memory'),
    max_tokens=2_000,
    max_lines=200,
)
The snapshot is added to the conversation’s message history, so every later request sends it unchanged and the cached prompt prefix holds. Memory adds one on the first request of a run, with the user’s prompt, and only when memory changed since the latest snapshot in the history (or there is none yet). A conversation therefore carries one snapshot per run in which memory changed; earlier ones stay where they were sent, and the default guidance tells the model that a later <memory> block for the same memory supersedes its earlier ones. When memory is emptied, the new snapshot says so, under the memory’s heading. An empty snapshot is skipped only in a fresh conversation, whose history is just the current prompt: anything earlier, such as an older snapshot a provider still sends after another provider’s compaction or a summary that kept memory’s facts, could still show what was deleted. A snapshot before the latest compaction boundary no longer counts, so the next run records the current memory again.
New or changed memory is not added after tool results, where a model could read it as a new message from the user. The one exception is restoring the run’s own snapshot when compaction drops it in the middle of a tool loop, described below. Memory that changes during a run, through write_memory or an external update, reaches the model with the next user prompt; the model’s own writes are already in the conversation as its tool calls. A snapshot is only added before the model has responded in the run, so a run that starts without a prompt from history ending in tool results or a response (resuming after a deferred tool approval, or continuing a provider-suspended response), or a Memory loaded mid-run with defer_loading=True, adds none, even if a hook retries its first request; if compaction drops the snapshot such a run started with, that same snapshot is enqueued again, even when the history has none yet: memory reaches the model with the next prompt. A run with no prompt and no tool results, such as agent.run() on an empty history, gets its snapshot on that request. If an earlier capability’s before_model_request retries the run’s first request, the snapshot follows the retry feedback, still ahead of any response. Every snapshot is enqueued, so UI adapters stream it as an EnqueuedMessagesEvent.
Stored memory and the listed file names go into the snapshot as data: the framework’s framing tags in them, such as <system>, and <memory> itself are escaped, so memory can’t close its block or read as the application speaking.
Snapshots are part of the conversation history and reach UI clients: UI adapters stream each new one as it is added and include it in the history they send. Keep that in mind when memory holds anything the user of the UI should not see.
Snapshots are recognized by the metadata on their TextContent, {'origin': 'pydantic-ai-harness.memory.v1', 'scope': ..., 'id': ...} (the hashed scope and the capability’s id), never by their text. A history that loses that metadata on the way through a UI client, as a Vercel AI round trip does, gets a fresh snapshot on every run, and its earlier snapshots then look like user messages to SummarizingCompaction, which keeps them with keep_user_messages. Keep the history on the server when that matters. Snapshots saved by earlier releases, which marked them with a plain string, are recognized and kept.
When combining it with compaction, list compaction before Memory, so Memory sees the history compaction leaves. If compaction drops the snapshot a run started with, Memory enqueues that same snapshot again on the same request, without reading the store again. It lands at the end of the request being sent, after its tool results, which is the one place every compaction keeps, native compaction included; on a later run’s first request it records the current memory again if needed.
Set inject_memory=False to keep memory out of the conversation entirely. The tools remain available, and the model can fetch memory only when it needs it. Snapshots that earlier runs added stay in the history:
from pydantic_ai_harness import Memory
from pydantic_ai_harness.memory import FileStore

memory = Memory(FileStore('.agent-memory'), inject_memory=False)
With injection_errors='ignore' (the default), a store failure skips automatic injection and emits content-safe telemetry. Spans record the backend type and a hash of the resolved scope; successful injection records counts and whether a snapshot was appended (memory.appended), and failures record the exception type. They do not record memory content. Set injection_errors='raise' when a run must fail rather than proceed without injected memory. Namespace and store resolver failures always propagate. This setting controls automatic injection only. In the tools, a path that resolves outside the store asks the model to retry, and a workspace failure during write_memory or delete_memory is returned as a failed tool call unless the workspace is unavailable. The failure message names only the memory file, so backend paths and the namespace stay out of the model’s context. A write or delete that keeps conflicting with concurrent changes asks the model to retry. Any other store error ends the run.
Writes and deletes are compare-and-swap: a mutation based on stale content fails with a conflict instead of overwriting a concurrent edit. A replayed tool call is not applied twice, and reusing its operation identifier with different arguments raises MemoryOperationConflictError. Custom stores must make both checks atomic inside write and delete rather than composing separate read and write calls.
Every read call passes a finite max_chars and every list_paths call a finite limit. When the file is longer, a store returns the bounded prefix with MemoryFile.truncated=True and the version of the complete file. A custom SearchableMemoryStore.search must honor max_file_chars as well as the result limits. read_memory marks a truncated result. write_memory refuses to append to or edit a file larger than max_memory_size, because it would build the new content from a partial read; edit or replace that file in the backing store first.
| Store | Persistence and concurrency boundary |
|---|---|
InMemoryStore() | Process lifetime; atomic across tasks using that store instance. Receipts for the 1,024 most recent mutations are kept. |
FileStore(directory) | Markdown files in the run’s workspace, or in workspace=. Versions are content hashes, and receipts for recent mutations are kept beside the files. One writer per directory. |
SqliteMemoryStore(database=...) | Durable single-host storage; compare-and-swap and idempotency are enforced in database transactions. Receipts accumulate in the memory_operations table until you delete old rows. |
PostgresMemoryStore(pool) | Durable shared storage; compare-and-swap and idempotency are enforced in database transactions. Receipts accumulate in the {table}_operations table until you delete old rows. The caller owns the pool lifecycle. |
PixeltableMemoryStore(table_name=...) | Durable shared storage in a Pixeltable catalog; receipts and table history are retained. Install [pixeltable] on Python 3.11 to 3.14. See the Pixeltable guide. |
from pydantic_ai_harness import Memory
from pydantic_ai_harness.memory import FileStore, SqliteMemoryStore

local_memory = Memory(FileStore('.agent-memory'))
sqlite_memory = Memory(SqliteMemoryStore(database='.agent-memory.db'))
SqliteMemoryStore can instead use a caller-owned sqlite3.Connection. Because operations run off the event loop, create that connection with check_same_thread=False and manage its lifecycle in the application. The connection must be dedicated to the store and idle at the start of every operation; a call fails rather than commit or roll back an active caller transaction.
If a memory path resolves outside its store, the tool asks the model to correct the path. A corrupt receipts file produces a warning and starts a fresh operation journal; restore a backup if replay protection for earlier operations matters.
FileStore keeps receipts for its 1,024 most recent mutations in .memory-operations.json beside the Markdown files, so a replayed tool call is not applied twice; copy it with them. It serializes its own operations but not those of another store or process writing the same directory, so share one FileStore instance, or use SqliteMemoryStore or PostgresMemoryStore for concurrent writers. Editing a Markdown file outside the capability changes its version, so a write based on the old content fails with a conflict. FileStore listings and searches skip symlinked directories, including links that point outside the store.
PostgresMemoryStore accepts the driver-neutral PostgresPool protocol, so the harness does not require a particular PostgreSQL driver. Install and manage the driver in your application, for example:
pip install asyncpg
uv add asyncpg
import asyncpg

from pydantic_ai_harness import Memory
from pydantic_ai_harness.memory import PostgresMemoryStore


async def build_memory() -> tuple[Memory[None], asyncpg.Pool]:
    pool = await asyncpg.create_pool('postgres://localhost/app')
    memory = Memory(PostgresMemoryStore(pool))
    return memory, pool
Call build_memory during application startup and close the returned pool during shutdown. The store does not manage it.
Use a namespace resolver when one Agent serves multiple users. It runs once per run from your typed dependencies, and its result is hidden from the model-facing tool schema.
from dataclasses import dataclass

from pydantic_ai import Agent
from pydantic_ai.workspaces import LocalWorkspaceBackend
from pydantic_ai_harness import Memory
from pydantic_ai_harness.memory import FileStore


@dataclass
class AppDeps:
    user_id: str


agent = Agent(
    'anthropic:claude-opus-5-5',
    deps_type=AppDeps,
    capabilities=[
        Memory(
            FileStore('.', workspace=LocalWorkspaceBackend('/var/lib/myapp/memory')),
            namespace=lambda ctx: ctx.deps.user_id,
        )
    ],
    defer_model_check=True,
)
Namespace isolation controls which records the capability addresses. It is not an authorization system for a custom or shared backing store. Validate the identity in application dependencies, restrict backend credentials, and ensure custom stores cannot escape the resolved namespace.
A namespace is one or more /-separated segments of letters, digits, _, -, and .; a segment of . or one containing .. raises ValueError when the run starts. FileStore keeps each namespace in a directory, so on a case-insensitive filesystem, the macOS and Windows default, Alice and alice share files: normalize the case of the identity before returning it. Windows also drops trailing dots from directory names, so there alice. and alice share files too. Spans record memory.scope_hash, an unsalted hash of the namespace and agent_name. It keeps the identity out of telemetry, but anyone who can guess an identity can confirm it.
When the agent is not the only writer, for example when people can also edit what it remembered about them in your product, a store can record who made each write. InMemoryStore, SqliteMemoryStore and PostgresMemoryStore implement MetadataMemoryStore: write_with_metadata stores a Mapping[str, str] with the content, and read returns it as MemoryFile.metadata. Set write_metadata on Memory to record metadata with the model’s writes, either as a mapping or as a callable that resolves it from the run for each write. Your application supplies it and it never appears in a tool schema, so the model cannot choose its own provenance. The callable runs inside each write_memory call, after the check for a replayed call, so unlike store_resolver and namespace it need not be deterministic under Temporal or Prefect.
The model’s files live at {namespace}/{agent_name}/{file}, so with the default agent_name='main' your UI edits {user_id}/main/MEMORY.md to change the notebook the agent reads.
from dataclasses import dataclass

from pydantic_ai import Agent
from pydantic_ai_harness import Memory
from pydantic_ai_harness.memory import SqliteMemoryStore


@dataclass
class AppDeps:
    user_id: str


store = SqliteMemoryStore(database='.agent-memory.db')
agent = Agent(
    'anthropic:claude-opus-5-5',
    deps_type=AppDeps,
    capabilities=[
        Memory(
            store,
            namespace=lambda ctx: ctx.deps.user_id,
            write_metadata=lambda ctx: {'updated_by': 'agent', 'user_id': ctx.deps.user_id},
        )
    ],
    defer_model_check=True,
)


async def save_from_editor(user_id: str, content: str, version: str | None) -> None:
    """Save what the user typed in your memory editor, recording that they typed it."""
    await store.write_with_metadata(
        f'{user_id}/main/MEMORY.md',
        content,
        expected_version=version,
        metadata={'updated_by': 'ui', 'user_id': user_id},
    )


async def last_written_by(user_id: str) -> str | None:
    file = await store.read(f'{user_id}/main/MEMORY.md', max_chars=65_536)
    return None if file is None or file.metadata is None else file.metadata.get('updated_by')
Metadata describes the write that produced the current version:
- It is written in the same transaction as the content (under the same lock for
InMemoryStore), and each write replaces it. A write without metadata, including the model’s writes whenwrite_metadatais unset, records none, so after the agent edits a file the user typed, the file no longer readsupdated_by='ui'. - A delete removes it. A replayed tool call returns the original receipt, which carries no metadata, and leaves the stored metadata as it is;
readthe file for the metadata of its current version. Metadata is not part of the operation fingerprint, so a callable that resolves different metadata on a retry is not a conflict. - The bundled stores accept string keys and values without NUL characters, at most 4,096 characters as JSON, and
Memorychecks a fixedwrite_metadatamapping when it is constructed. An empty mapping is no metadata. It stays out of the model’s context, the memory spans, and the memory snapshot a durable engine journals. PostgresMemoryStorekeeps it in awrite_metadata JSONBcolumn of its table, so the application can query it, for exampleWHERE write_metadata->>'updated_by' = 'ui'.SqliteMemoryStorekeeps it as JSON text in awrite_metadatacolumn. Both add the column to an existing table on first use, and rows written before then read asmetadata=None.
Memory(write_metadata=...) raises UserError at construction, or when the run starts for a store_resolver, if the store does not implement MetadataMemoryStore, rather than drop the metadata. FileStore does not implement it: a sidecar file could not change in one atomic step with the Markdown, and the model’s file tools could edit it. PixeltableMemoryStore does not implement it either.
A store records write metadata when it has a write_with_metadata method, so a custom store opts in by implementing the one MetadataMemoryStore declares. It must store the metadata in the same atomic step as the content, and the store’s write must record none, as the bundled stores’ write does by calling write_with_metadata with metadata=None. A custom store that implements only MemoryStore keeps working as before without metadata. A subclass of a bundled store that overrides write keeps working too; with write_metadata set, Memory calls write_with_metadata instead, so override that method as well.
An agent can carry several Memory capabilities at once, for example a personal notebook plus a shared org notebook. Four constraints apply:
- Give each instance a distinct
id. Instances that share the defaultid='memory'are one capability to the agent: unless they share one store instance and the same settings, constructing the agent raisesUserError. - Give each instance a distinct
agent_nameornamespacewhen they should keep separate notes. The resolved scope is where an instance stores its files; two instances with the same scope (and store) read and write the same notebook. Snapshots are tracked by scope andidtogether, so each instance records and supersedes only its own snapshots, even when two share a scope. - All instances define the same tool names, so wrap every instance but one in
prefix_toolsto keep the tool schemas distinct. - Set a distinct
headingon each instance so the model sees the blocks as separate sections.agent_nameis a storage key and never appears in the prompt, so it can’t label them.
from pydantic_ai import Agent
from pydantic_ai.workspaces import LocalWorkspaceBackend
from pydantic_ai_harness import Memory
from pydantic_ai_harness.memory import FileStore

store = FileStore('.', workspace=LocalWorkspaceBackend('/var/lib/myapp/memory'))
agent = Agent(
    'anthropic:claude-opus-5-5',
    capabilities=[
        Memory(store, heading='Your notes'),
        Memory(store, agent_name='org', heading='Org notes', id='org_memory').prefix_tools('org'),
    ],
    defer_model_check=True,
)
search_memory performs literal text search and always applies three bounds:
max_search_resultslimits returned matches, default 10.max_search_result_charslimits the combined scope-relative filename and snippet text, default 4,000 characters.max_search_fileslimits how many files a fallback scan may inspect, default 1,000.
The bundled stores implement SearchableMemoryStore. A store counts as searchable when it has a search method, so a custom store’s search must take the arguments SearchableMemoryStore.search declares. For a custom store that implements only MemoryStore, search_memory requests at most max_search_files + 1 paths, scans at most max_search_files, and performs bounded reads. Lexical scoring uses only each scope-relative filename and its bounded content; tenant namespaces and agent names never affect relevance. Implement the optional search protocol for an indexed or semantic backend while preserving the same tenant boundary and result limits. Semantic ranking is not built in.
The bundled stores search only the files directly in the run’s scope and skip a deeper scope nested under it, such as namespace acme/main under namespace acme. The fallback scan for a custom store skips them too, but they still count toward the max_search_files + 1 paths it requests.
Scoring runs on the event loop and yields after each file, so a scan near the limits slows that search without stalling other runs in the process.
Before backend dispatch, queries are limited to 1,000 characters and 32 unique whitespace-separated terms. Repeated case-insensitive terms are collapsed so they cannot inflate scoring or scan work.
from pydantic_ai_harness import Memory
from pydantic_ai_harness.memory import FileStore

Memory(
    FileStore('.agent-memory'),
    store_resolver=None,               # optional per-run store resolver
    agent_name='main',                 # storage segment inside the namespace; never shown to the model
    heading='',                        # optional heading on guidance and injected content
    namespace='',                      # string or per-run resolver
    inject_memory=True,                # False keeps memory out of the conversation
    max_tokens=2_000,                  # finite approximate total injection budget
    max_lines=200,                     # additional main-notebook line limit
    max_memory_size=65_536,            # per-file read, search, and write boundary
    max_search_results=10,
    max_search_result_chars=4_000,
    max_search_files=1_000,
    injection_errors='ignore',         # or 'raise'
    guidance=None,                     # None uses the default notebook guidance
    write_metadata=None,               # needs a MetadataMemoryStore; see Write metadata
    scanner=None,                      # an ArtifactScanner; see Scanning memory
)
Register Memory as a custom capability type when constructing an agent from a Python spec:
from pydantic_ai import Agent
from pydantic_ai_harness import Memory

agent = Agent.from_spec(
    {
        'model': 'anthropic:claude-opus-5-5',
        'capabilities': [
            {'Memory': {'backend': 'file', 'directory': '.agent-memory'}},
        ],
    },
    custom_capability_types=[Memory],
    defer_model_check=True,
)
The serializable backends are memory, file, and sqlite. A namespace callable and a live PostgreSQL pool must be configured in Python.
| Execution mode | Support |
|---|---|
Normal Agent.run calls | Supported with automatic injection or on-demand tools. |
| Temporal and Prefect | Automatic snapshot loading is a journaled capability operation. On replay, the recorded snapshot is reused. store_resolver and a callable namespace run before that operation, so they must be deterministic and free of backend I/O; a per-tenant resolver that queries a backend is not workflow-safe. |
| DBOS | Automatic snapshot loading and each memory tool call are DBOS steps. A recovered or forked workflow reuses their recorded results instead of reading or writing the store again. |
Memory carries the stable default id='memory', so durable recovery works without configuration. The memory backend and workflow state backend remain independent: durable execution does not make an in-memory notebook persistent.
Each model request that uses automatic snapshot loading records one bounded snapshot result in workflow history, so choose max_memory_size and max_tokens with the engine’s history limits in mind.
Memory is model-written, untrusted content that can re-enter future prompts. Keeping it in a delimited user-role part lowers its authority relative to model instructions, but this is not a hard prompt-injection boundary. In stored content, the < of a <memory> or </memory> tag, in any case or spacing, is injected as <, so stored text cannot end the block early. Use inject_memory=False when less-trusted actors can write to the store, and expose memory only through application-controlled retrieval when stronger isolation is required. Do not store secrets unless the backend, retention policy, and access controls are appropriate. Sanitize content before rendering it into another trust domain.
Memory records do not carry source citations. To record who wrote a file, such as the user in your product or the agent, use write metadata with a MetadataMemoryStore rather than a header in the note. Metadata records which writer produced the current version; it does not establish that a remembered claim is true, and neither does optimistic concurrency, which prevents lost updates.
Pass an ArtifactScanner to check what the model writes, and what later sessions load, for prompt injection, credential exfiltration, HTML comments, and invisible characters:
from pydantic_ai_harness import ArtifactScanner, Memory

memory = Memory(scanner=ArtifactScanner())
With a scanner set:
write_memoryrefuses flagged text with a tool failure that names the threats but does not quote the text, and stores nothing. Only the text being written is scanned, so a correction that removes a passage still succeeds.- A flagged
MEMORY.mdis left out of the injected snapshot, with a notice in its place, so the model can tell the user. The list of other files is still shown. read_memoryrefuses a flagged file, andsearch_memoryreplaces a flagged snippet with a notice.- Each decision records a zero-duration
artifact_scan flaggedspan, and thememory.injectspan gainsmemory.main_withheld.
The scan runs outside the durable operations Memory routes its tools through, so under Temporal, Prefect, or DBOS a refusal fails the tool call rather than an operation the engine would retry.
Files that FileSystem’s read_file reads in place of read_memory, or that other tools open, are not scanned. The scan is pattern matching: it misses paraphrased instructions and can flag a note that quotes an attack, so treat it as one layer next to inject_memory=False for less-trusted writers.
The public module exports Memory, MemoryToolset, the bundled stores, the store protocols, mutation and search result models, and conflict exceptions. Import them from pydantic_ai_harness.memory.
Bases: AbstractCapability[AgentDepsT]
Persistent agent memory across sessions.
A snapshot of MEMORY.md is recorded in the conversation as user-role data,
once per run in which it changed, and longer topic files are available
through read_memory and search_memory. When a FileStore keeps the
files in the run’s workspace, read_memory steps aside for FileSystem’s
read_file, and the snapshot gives the directory. Automatic snapshot
loading is journaled by durability engines that support capability
operations.
Storage backend. The default persists only for the process lifetime.
FileStore keeps Markdown files in the run’s workspace, or in a workspace of its own.
Type: MemoryStore Default: field(default_factory=InMemoryStore)
Optional per-run store resolver. Resolver failures always propagate.
Type: Callable[[RunContext[AgentDepsT]], MemoryStore] | None Default: None
Storage segment that isolates memory within a namespace. Part of the scope key only; never rendered into the model-facing memory block.
Type: str Default: 'main'
Markdown heading for rendered guidance and the injected memory block,
rendered as ## {heading} when set. The default is empty: the block already
sits inside <memory> markers, so none is added. Set a distinct value per
instance when several Memory capabilities share one agent (for example
heading='Team notes') so the model can tell the blocks apart.
Type: str Default: field(default='', kw_only=True)
Static or per-run tenant namespace, never exposed as a tool argument.
Type: str | Callable[[RunContext[AgentDepsT]], str] Default: ''
Inject stored memory when true; otherwise inject static tool guidance only.
Type: bool Default: True
Approximate total token ceiling for the complete injected memory section.
Type: int Default: 2000
Maximum number of MEMORY.md content lines considered for injection.
Type: int Default: 200
Per-file character boundary for backend reads, search, and writes.
Type: int Default: 65536
Maximum matches returned by one search.
Type: int Default: 10
Maximum combined snippet characters returned by one search.
Type: int Default: 4000
Maximum files scanned by one search.
Type: int Default: 1000
Override injected usage guidance; '' disables guidance.
Type: str | None Default: None
Whether store failures during automatic injection are ignored or raised.
Type: Literal[‘ignore’, ‘raise’] Default: 'ignore'
Metadata to record with each write_memory write, such as {'updated_by': 'agent'}, or a
callable that resolves it from the run for each write.
The application supplies it; it is never a tool argument. It needs a MetadataMemoryStore, and
raises UserError when the store, or the one store_resolver returns, is not one. When unset,
the model’s writes to such a store record no metadata.
Type: Mapping[str, str] | WriteMetadataFunc[AgentDepsT] | None Default: None
Scan memory for prompt injection, credential exfiltration, and hidden content, or None (the default)
to store and load it unscanned.
write_memory refuses flagged text, a flagged MEMORY.md is left out of the injected snapshot with a
notice in its place, read_memory refuses a flagged file, and a flagged search_memory snippet is
replaced with a notice. Files read with FileSystem’s read_file instead of read_memory are not
scanned.
Type: ArtifactScanner | None Default: None
@async
def for_run(ctx: RunContext[AgentDepsT]) -> Memory[AgentDepsT]
Return a clone with scope resolution isolated to this run.
Memory[AgentDepsT]
@async
def before_run(ctx: RunContext[AgentDepsT]) -> None
Note what the run starts from, and fail it when a FileStore has no workspace to keep its files in.
Read here rather than in for_run, which a durable engine also calls to rebuild the capability inside an
activity, where the run’s prompt and history aren’t carried.
def resolve_scope(ctx: RunContext[AgentDepsT]) -> tuple[MemoryStore, str]
Return the cached run scope, or resolve one for direct toolset use.
A FileStore without a workspace of its own is bound to ctx.workspace.
@classmethod
def combine(
    cls,
    capabilities: Sequence[AbstractCapability[AgentDepsT]],
) -> AbstractCapability[AgentDepsT]
Two under one id are one notebook stated twice; two that disagree raise rather than merge.
A field-by-field merge of two notebooks would keep one and drop the other.
AbstractCapability[AgentDepsT]
def get_toolset() -> AgentToolset[AgentDepsT] | None
Provide the stable memory toolset, shared with every per-run copy.
AgentToolset[AgentDepsT] | None
def get_instructions() -> AgentInstructions[AgentDepsT] | None
Provide trusted static guidance about using memory.
Stored memory is added separately as user-role context by
before_model_request so model-written content is not placed in the
instruction channel. The guidance is the same in every run, so it stays
static and inside the cached prefix; when read_file reads the files in
place of read_memory, the injected snapshot says where they are.
AgentInstructions[AgentDepsT] | None
@async
def before_model_request(
    ctx: RunContext[AgentDepsT],
    request_context: ModelRequestContext,
) -> ModelRequestContext
Record a memory snapshot in history at the start of a run, when memory changed since the last one.
The snapshot is enqueued, so it is added to the conversation once and sent unchanged with every later request: history only ever grows. It is only added before the model has responded in this run, which keeps it with the user’s prompt: later requests carry tool results, where a block of user-channel text reads as a new message from the user. If compaction later in the run drops the snapshot the run started with, the same snapshot is enqueued again, without reading the store again.
@classmethod
def from_spec(
    cls,
    *,
    backend: Literal['memory', 'file', 'sqlite'] = 'memory',
    directory: str = '.agent-memory',
    database: str = '.agent-memory.db',
    agent_name: str = 'main',
    heading: str = '',
    namespace: str = '',
    inject_memory: bool = True,
    max_tokens: int = 2000,
    max_lines: int = 200,
    max_memory_size: int = 65536,
    max_search_results: int = 10,
    max_search_result_chars: int = 4000,
    max_search_files: int = 1000,
    guidance: str | None = None,
    injection_errors: Literal['ignore', 'raise'] = 'ignore',
    id: str | None = 'memory',
    description: str | None = None,
    defer_loading: bool = False,
) -> Memory[AgentDepsT]
Construct a memory capability from serializable options.
Memory[AgentDepsT]
@classmethod
def get_serialization_name(cls) -> str | None
Return the name used by custom capability specs.
Bases: FunctionToolset[AgentDepsT]
Scoped read/write/delete/search tools with CAS and durable idempotency.
The stable ID, its capability’s (memory by default), lets Temporal and Prefect wrap this static toolset.
Memory passes operations so that each tool call runs as one of its
durable operations, whose result durable execution records instead of
repeating the call on recovery, including on DBOS, which runs function
tools in workflow code. A MemoryToolset built without operations runs
its tools directly.
@async
def get_instructions(ctx: RunContext[AgentDepsT]) -> list[InstructionPart] | None
Say where the memory files are when read_memory steps aside for the run’s file reader.
Returned from the first request on, empty when it has nothing to say, so the block never first appears
mid-conversation: a file reader that joins mid-run appends its text instead. The text’s length is
reserved in max_tokens from configuration and the run’s scope alone.
@async
def write_memory(
    ctx: RunContext[AgentDepsT],
    content: str,
    file: str = MAIN_FILENAME,
    old_text: str | None = None,
) -> MemoryWriteResult
Write persistent memory by appending or uniquely replacing text.
Omit old_text to append, creating the file when necessary. Pass
old_text to replace exactly one matching passage; use an empty
content to remove that passage. Keep short durable facts in
MEMORY.md, and longer or evolving topics in separate files. Update
stale entries rather than adding contradictory duplicates.
MemoryWriteResult
ctx : RunContext[AgentDepsT]
Framework-provided run context.
content : str
Text to append, or replacement text for old_text.
file : str Default: MAIN_FILENAME
Memory filename; defaults to MEMORY.md.
Exact passage to replace, which must occur once.
@async
def read_memory(ctx: RunContext[AgentDepsT], file: str) -> str
Read a bounded prefix of one memory file.
Memory may be stale background context, so verify volatile facts before relying on them.
ctx : RunContext[AgentDepsT]
Framework-provided run context.
file : str
Memory filename returned by injection or search.
@async
def delete_memory(ctx: RunContext[AgentDepsT], file: str) -> MemoryDeleteResult
Delete a non-main memory file that is no longer useful.
MEMORY.md cannot be deleted; remove or correct its text with
write_memory instead.
MemoryDeleteResult
ctx : RunContext[AgentDepsT]
Framework-provided run context.
file : str
Memory filename to delete.
@async
def search_memory(ctx: RunContext[AgentDepsT], query: str) -> MemorySearchResponse
Search memory files in the current tenant and agent scope.
Results contain bounded snippets; read the file when a larger bounded excerpt is relevant.
MemorySearchResponse
ctx : RunContext[AgentDepsT]
Framework-provided run context.
query : str
Terms to find in memory filenames and content.