Tool Output Limits
ToolOutputLimits reduces a tool return that is large enough to dominate the context
window. Tool returns persist in history as ToolReturnParts, so an oversized one is re-sent
on every later model request, paying its token cost for the rest of the run. This capability
intercepts a return when it is produced, reduces it once, and lets the reduced form persist —
the reduction is not recomputed per request.
While Pydantic AI Harness is on 0.x releases, the API may change between minor releases; when it does, deprecation warnings and release-note migration guidance tell you (or your agent) exactly how to upgrade. See the version policy.
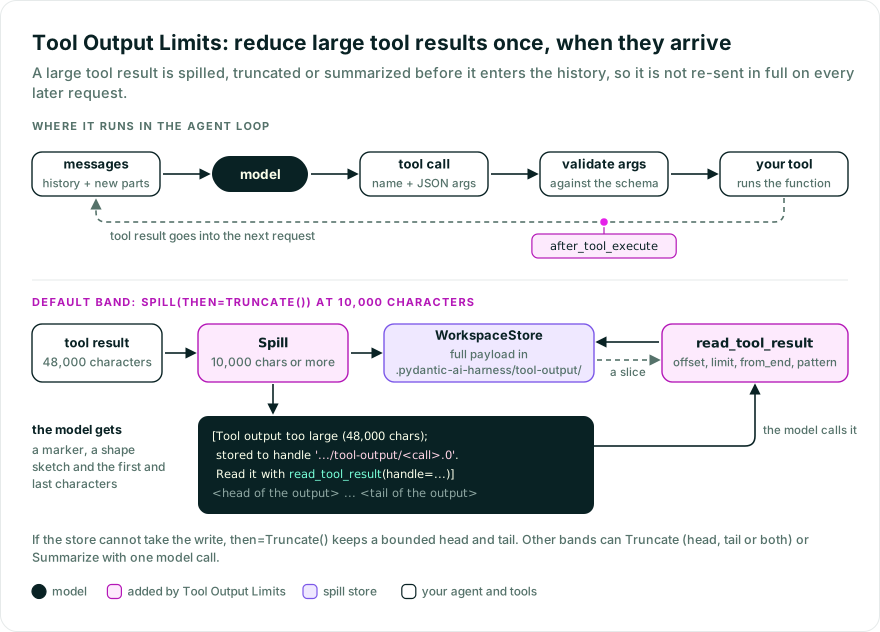
A tool can return a payload large enough to dominate the context window: a big file read, a verbose log, a large JSON document. Because tool returns persist in history, an oversized one is re-sent on every later model request, paying its token cost for the rest of the run.
| Mode | Cost | Lossy? | What the model gets |
|---|---|---|---|
Truncate | zero-LLM | yes | A head / tail / head+tail clamp of the text |
Spill | zero-LLM | no | A handle + preview + shape sketch; full payload read back on demand |
Summarize | one LLM call | yes | A size-gated summary (inherits the run’s model by default) |
Spill is lossless: the full payload is persisted and the model reads slices of it through
the registered read_tool_result(handle, offset, limit, from_end, pattern) tool.
That tool is bounded: offset >= 0, limit clamped to a built-in line cap, the joined output
capped, and pattern is a literal substring (not a regex), so a model-supplied value cannot
hang the host with catastrophic backtracking.
Construct an Agent with ToolOutputLimits() in its capabilities. With no arguments it
uses the default band: spill returns of 10,000 characters or more, with a bounded truncation
fallback if the store cannot accept the write. Spills go to the run’s
workspace, so attach one
(Spill store has other options):
from pydantic_ai import Agent
from pydantic_ai.capabilities import LocalWorkspace
from pydantic_ai_harness import ToolOutputLimits

agent = Agent('anthropic:claude-opus-5-5', capabilities=[LocalWorkspace('.'), ToolOutputLimits()])
The capability registers a single read_tool_result tool so the model can page back into any
spilled payload. Its own returns are exempt from reduction. With FileSystem on the agent,
read_file takes its place for spills in the run’s workspace, and its reads of spills are exempt
too (Reading spills with FileSystem). Core’s load_capability
and search_tools returns are never reduced either: core reads them back from history to know which
on-demand capabilities are loaded and which tools are revealed.
Configure an ordered list of size bands. Each band is a (over, action) pair: when a
return’s measured size reaches over, its action runs. The band with the largest threshold
that fits wins; anything below the smallest threshold passes through.
from pydantic_ai import Agent
from pydantic_ai.capabilities import LocalWorkspace
from pydantic_ai_harness import ToolOutputLimits
from pydantic_ai_harness.tool_output_limits import Band, Spill, Summarize, Truncate

agent = Agent(
    'anthropic:claude-opus-5-5',
    capabilities=[
        LocalWorkspace('.'),
        ToolOutputLimits(
            bands=[
                Band(over=100_000, action=Spill()),      # huge: keep losslessly, read back on demand
                Band(over=20_000, action=Summarize()),    # large: compress with the run's model
                Band(over=5_000, action=Truncate()),      # medium: cheap clamp
            ],
            # below 5,000: passthrough
        )
    ],
)
The default band, when you pass no bands, is Spill(then=Truncate()) at a 10,000-character
threshold: lossless when a store accepts the write, otherwise truncated to max_chars. Neither
calls a model.
Passthrough() is an explicit no-op action for bands or per_tool lists, leaving matching
returns untouched.
When an agent gets two ToolOutputLimits with the same id, their bands merge into one list
that is still matched largest threshold first. At a threshold both state, the later band wins.
Every action takes an optional then, applied when the action cannot run: a Spill whose
store errors (for example, the workspace is read-only), a Truncate / Summarize on a binary
payload, a Summarize whose model call raises. then chains, so
Summarize(then=Spill(then=Truncate())) degrades summarize -> spill -> truncate. Store and
summarizer exceptions that would otherwise fall back silently are logged at WARNING on the
pydantic_ai_harness.tool_output_limits logger, with the exception type and traceback, before
the fallback runs.
per_tool replaces the global band list for named tools (file reads to head, logs to
tail); tool_filter (a ToolSelector) scopes which tools the capability touches at all.
from pydantic_ai import Agent
from pydantic_ai.capabilities import LocalWorkspace
from pydantic_ai_harness import ToolOutputLimits
from pydantic_ai_harness.tool_output_limits import Band, Truncate, TruncationStrategy

agent = Agent(
    'anthropic:claude-opus-5-5',
    capabilities=[
        LocalWorkspace('.'),
        ToolOutputLimits(
            per_tool={
                'read_file': [Band(over=8_000, action=Truncate(strategy=TruncationStrategy.head))],
                'run_shell': [Band(over=8_000, action=Truncate(strategy=TruncationStrategy.tail))],
            },
            tool_filter=['read_file', 'run_shell', 'search'],
        )
    ],
)
TruncationStrategy has three members: head (keep the first characters, good for headers and
schemas), tail (keep the last characters, good for build and test output where errors land
last), and head_tail (keep both ends, elide the middle — the default).
Set Truncate(keep_tail_lines=N) to reserve the final N lines before allocating the rest of
the character budget. The default is zero, which leaves existing truncation behavior unchanged.
from pydantic_ai_harness.tool_output_limits import Band, ToolOutputLimits, Truncate, TruncationStrategy

truncate = Truncate(max_chars=4_000, strategy=TruncationStrategy.head, keep_tail_lines=2)
limits = ToolOutputLimits(bands=[], per_tool={'run_command': [Band(over=4_000, action=truncate)]})
With head, the remaining content budget keeps the beginning of the output. With
head_tail, it is split 2:3 between the beginning and the text immediately before the
reserved lines. tail continues to keep the end. Markers and all retained characters count
toward max_chars.
The cap takes priority. If the requested lines exceed it, truncation falls back to the
usual tail strategy; if they fit but a full marker would displace them, the result is a
bare tail slice within the cap. This does not invoke then or guarantee that an oversized
control trailer remains intact.
Lines are separated by LF or CRLF, and their existing endings are retained. A terminating
newline does not add a line, but a blank final line counts. Requesting more lines than exist
selects the whole text, subject to the same cap. Negative keep_tail_lines values are rejected.
This applies to the text after serialization and optional ANSI stripping, independently
for ToolReturn.return_value and textual content. Binary fallbacks are unchanged.
Tail-line selection adds no telemetry spans: it is a slicing choice within the existing
tool-result reduction, rather than a separate operation.
Keep Shell’s native max_output_chars above the ToolOutputLimits thresholds. Use
tail truncation for moderate command output and Spill for large output:
from pydantic_ai import Agent
from pydantic_ai.capabilities import LocalWorkspace

from pydantic_ai_harness.shell import Shell
from pydantic_ai_harness.tool_output_limits import (
    Band,
    Spill,
    ToolOutputLimits,
    Truncate,
    TruncationStrategy,
)

tail = Truncate(max_chars=4_000, strategy=TruncationStrategy.tail)
agent = Agent(
    'anthropic:claude-opus-5-5',
    capabilities=[
        LocalWorkspace('.'),
        Shell(allowed_commands=['git', 'rg', 'pytest'], max_output_chars=100_000),
        ToolOutputLimits(
            bands=[],
            per_tool={
                'run_command': [
                    Band(over=20_000, action=Spill(then=tail)),
                    Band(over=4_000, action=tail),
                ],
            },
        ),
    ],
)
Only run_command uses these bands; bands=[] leaves other tools to their native limits.
A tail slice retains an exit-code trailer when it fits in the retained suffix. It does not
guarantee that an entire line survives a small budget; head can remove the trailer.
Shell applies its native cap before ToolOutputLimits sees the result. With the spill
threshold below that cap, a natively truncated result is stored instead of being truncated
again, unless the store fails. The spill preview shows both ends and the model can use
read_tool_result to inspect the stored text.
Spilling preserves only the result received from Shell. It cannot recover content already
removed by the native cap. A preview can contain both spill and native truncation notices;
a native notice describes the stored result, not the shorter preview. A positive
Spill.preview_chars value controls the preview’s content budget; its header and omission
marker add to that length.
A ToolReturn carries a return_value and an optional content that core renders as a
separate, model-visible part which also persists in history. This capability measures and
reduces both with the same band logic (they spill to distinct handles). Text content is
reduced in place; non-text content (multimodal parts) that overflows is left unreduced with
a warnings.warn, since it cannot be safely truncated.
Spill keys (overflow_handle, overflow_bytes, overflow_content_handle) live in
ToolReturn.metadata alongside whatever the tool put there. A pre-existing mapping is copied
in with stringified keys; a pre-existing non-mapping value (a string, a dataclass, anything
that is not a Mapping) is kept under original_metadata rather than dropped. Either way the
caller’s own metadata survives a spill and is readable from metadata on the resulting
ToolReturnPart after Agent.run.
Thresholds are measured in characters by default. Set over_tokens=True to measure in
estimated tokens (the same ~4-chars-per-token heuristic as compaction); pass a
tokenizer callable for accuracy. Truncate.max_chars is always characters — truncation is a
character operation regardless of the threshold unit. The cap includes the truncation marker
and applies separately to each reduced text value. If the budget cannot fit both retained
content and a complete marker, truncation keeps the selected slice without a marker. A
non-positive cap returns an empty string. Set strip_ansi=True to strip ANSI escape sequences
from text returns before measuring and reducing.
A spilled structured return is stored as compact JSON: one long line. read_tool_result
pages by line, so page 1 returns the whole payload and page 2 is empty. Setting serializer
stores the value in a layout with real lines instead:
from pydantic_ai_harness.tool_output_limits import ToolOutputLimits, indented_json, json_lines

ToolOutputLimits(serializer=indented_json)  # one field per line
ToolOutputLimits(serializer=json_lines)  # one record per line
Use json_lines for tools that return lists of records: line N is record N, so page offsets
and pattern matches line up with whole records. Anything that is not a list-like sequence
falls back to indented_json — including a list wrapped in a dict, so return the list
directly for per-record paging. Use indented_json for everything else.
Any (value) -> str callable works too, but prefer the presets: they escape the Unicode
line separators (U+0085/U+2028/U+2029) that would otherwise knock read-back offsets off the
line grid. The serialized text is also what gets measured, so an indented layout can cross
a size band that compact JSON would not. Strings and binary returns are never serialized,
returns below the smallest band pass through untouched, and a serializer that raises or
returns non-text warns and falls back to compact JSON rather than losing the tool output.
bytes inside a structured return render as the text they decode to. When one of them is not
UTF-8 (a file read in binary mode, raw command output), every bytes value in the rendered
JSON is base64-encoded instead, which is how Pydantic AI encodes bytes in the tool returns it
sends to the model. json_lines makes that switch per record.
The default WorkspaceStore writes each spill as a file in the run’s workspace, under
.pydantic-ai-harness/tool-output/ in the working directory, which is git-ignored. With a
sandbox the files live in the sandbox. The handle is the file’s absolute path, so a file tool
such as FileSystem’s read_file can open it too, and replaces read_tool_result when it is
on the agent (Reading spills with FileSystem).
read_tool_result only opens handles inside the store’s directory.
To keep spills in a different workspace than the run’s, pass a backend:
from pydantic_ai.workspaces import LocalWorkspaceBackend
from pydantic_ai_harness.tool_output_limits import ToolOutputLimits, WorkspaceStore

spills_elsewhere = ToolOutputLimits(store=WorkspaceStore(workspace=LocalWorkspaceBackend('/var/spills')))
workspace= takes a backend, not the LocalWorkspace capability. Under a durable engine such
as Temporal it is written in-process, not through the workflow.
Spilled files are kept for the life of the workspace; they are not pruned by this capability.
When spills are files in the run’s workspace (the default WorkspaceStore(), without a
workspace= of its own) and FileSystem is on the agent, read_tool_result steps aside for
FileSystem’s read_file. The tool is marked with
unless_tool_kind
set to READ_FILE_KIND, so it is left out of every run step that has a tool of that kind. The
spill marker then names that tool as it is called in the run, with the spill’s path:
[Tool output too large (20,719 chars); stored to handle '/repo/.pydantic-ai-harness/tool-output/<run>/<call>.0'. Read it with read_file(path='/repo/.pydantic-ai-harness/tool-output/<run>/<call>.0').]
A read_file call whose path is under .pydantic-ai-harness/tool-output/ is exempt from
reduction, as read_tool_result is, so reading a spill back does not spill it again; read_file
bounds its own output. Other read_file calls are reduced as usual. read_tool_result is
recognized by its kind, READ_TOOL_RESULT_KIND, not its name, so a prefixed reader is exempt too.
WorkspaceStore(workspace=...), LocalFileStore and other OverflowStores keep spills where
FileSystem cannot see them, so with those read_tool_result stays.
Two gaps to know about:
read_filehas no equivalent ofread_tool_result’sfrom_end. Filtering bypatternmaps toFileSystem’ssearch_files(orgrep).- The decision is made from the store, not from
FileSystem’s access rules. AFileSystemwhosedenied_patternscover.pydantic-ai-harness/, or whoseallowed_patternsleave it out, still replacesread_tool_resultbut cannot open the spills. Pass a store with aworkspace=of its own, orLocalFileStore(), to keepread_tool_resultin that setup.
A read-only workspace cannot take spills: the spill warns and falls back to its then action (a
bounded truncation by default). When a band can spill and the run has no workspace for the store
to write to, the run fails at its start. For runs without a workspace, use LocalFileStore, which
writes to the host’s temp directory:
from datetime import timedelta

from pydantic_ai import Agent
from pydantic_ai_harness.tool_output_limits import LocalFileStore, ToolOutputLimits

store = LocalFileStore(cleanup_after=timedelta(hours=6))  # default: None = keep forever
agent = Agent('anthropic:claude-opus-5-5', capabilities=[ToolOutputLimits(store=store)])
The local store root is stable so a later agent or run by the same user can read a spill. Its security does not come from per-instance isolation:
- Without
base_dir, the root ispyai_harness_overflow-<euid>under the system temp directory. - The root itself cannot be a symlink. Before each read or write on POSIX, it must also be owned
by the current user. Group and other permission bits are removed (
0700). A symlinked or foreign-owned root raisesPermissionError; for a write, the band’sthenfallback runs. Windows has no uid, so it uses the unsuffixedpyai_harness_overflowroot and skips the ownership check. readresolves the target and rejects any path that escapes the root. Handle segments are sanitized so a crafted handle cannot traverse out.
Set cleanup_after to delete spills older than that age.
Any other backend (a blob store, a durable engine’s storage) implements the OverflowStore
protocol and is passed as store=...:
from typing import Protocol


class OverflowStore(Protocol):
    async def write(self, key: str, data: bytes) -> str: ...   # returns a handle
    async def read(self, handle: str) -> bytes: ...
A built-in Summarize call is a real request to the model, so its full usage — tokens and the
request itself — folds into the run’s ctx.usage, exactly like SummarizingCompaction. Its nested
run receives the parent limits unchanged except that a finite request limit reserves one request for
the pending parent request, and is filed under the parent run’s conversation_id.
By default Summarize inherits the running agent’s model (ctx.model). Pass a model id or
instance to Summarize(model=...) to override, or a summarize callable to bypass the
built-in prompt entirely. The summary_prompt template on the capability must contain both
{tool_name} and {output} placeholders.
With a durable-execution capability attached, spill writes and built-in model summarization are
journaled capability operations: a replay reuses the recorded handle, fallback, or summary instead
of writing or summarizing again. ToolOutputLimits carries the stable default
id='tool_output_limits', so durable recovery works without configuration.
Three details matter when choosing a band and store under durability. The output being spilled or
summarized is part of the journaled operation input, so on an engine that runs operations on a
worker, such as Temporal, it counts against the engine’s payload limit, as the tool’s own result
already does. A write that succeeds just before a worker crash, before the engine records it, runs
again on recovery, so a custom OverflowStore should treat a repeated write of the same key as an
overwrite. And a custom summarize callable runs directly rather than as a durable operation —
arbitrary callables cannot be reconstructed on the worker side — so it may be called again on
replay.
- Binary returns spill verbatim and are never stringify-truncated;
Truncate/Summarizeon binary fall through tothen. - Structured / nested returns spill (or summarize) by preference — truncating JSON produces
invalid JSON.
Spillincludes a one-line shape sketch of the top level. ModelRetryand tool errors never reach this hook (they are raised, not returned), so the model always gets the full error it needs to recover.- A large
ToolReturn.contentis reduced with the same bands asreturn_value; non-text content that overflows is left unreduced with a warning. - Multiple oversized returns in one step get distinct handles (keyed per
tool_call_id); retries get distinct handles too (keyed perretry), so a retried call never clobbers the earlier attempt’s spill.
- Distinct from compaction, which compresses or drops context already inside the window; this capability moves large tool outputs out of the window at production time.
- Writes spills through the run’s workspace, so they sit beside the files that FileSystem and Shell tools act on.
- Distinct from
ClampOversizedMessages, which clamps runaway model responses, not tool returns.
Bases: AbstractCapability[AgentDepsT]
Reduce oversized tool returns when they are produced, persisting the reduction.
A tool can return a payload large enough to dominate the context window. Tool returns
persist in history, so an oversized one is re-sent on every later request. This
capability intercepts a return in after_tool_execute, reduces it once, and lets the
reduced form persist — it is not recomputed per request.
Three reduction modes, freely combined through an ordered list of size bands:
Truncate: clamp to a character budget. Lossy, zero-cost.Spill: persist the full payload, hand the model a handle plus a preview. Lossless. The model reads it back withread_tool_result, or, when the spill is in the run’s workspace andFileSystemis on the agent, with itsread_file.Summarize: size-gated LLM summary. Inherits the run’s model by default.
The first band whose over threshold the measured size meets wins; smaller returns pass
through. per_tool replaces the band list for named tools; tool_filter scopes which
tools are touched at all. The default is Spill(then=Truncate()): lossless when a store
accepts the write, a bounded truncation otherwise.
ModelRetry and other errors never reach this hook (they are raised, not returned), so
error payloads the model needs to recover are never spilled or summarized.
Ordered size bands. The first band whose over threshold is met wins.
Type: Sequence[Band] Default: field(default_factory=_default_bands)
Per-tool band lists that replace bands for the named tools.
Type: Mapping[str, Sequence[Band]] Default: field(default_factory=(dict[str, Sequence[Band]]))
Which tools this capability touches. Non-matching tools always pass through.
Type: ToolSelector[AgentDepsT] Default: 'all'
Measure band thresholds in estimated tokens instead of characters.
Type: bool Default: False
Optional (str) -> int tokenizer for over_tokens. Defaults to a ~4-char heuristic.
Type: Callable[[str], int] | None Default: None
Backend for spilled payloads.
Defaults to a WorkspaceStore in the run’s workspace. When the bands can spill and no store
has a workspace to write to, the run fails at its start: attach a workspace, or pass
store=LocalFileStore() to keep spills on this machine.
Type: OverflowStore | WorkspaceStore | None Default: None
Strip ANSI escape sequences from text returns before measuring and reducing.
Type: bool Default: False
Prompt template for Summarize. Must contain {tool_name} and {output}.
Type: str Default: _DEFAULT_SUMMARY_PROMPT
Render a structured (non-string, non-binary) return to the text that is measured,
previewed, spilled, and read back. When unset, structured returns render as compact
JSON, which puts the whole value on one line; the indented_json and json_lines
presets make large spills pageable by line through read_tool_result. A return that
stays under every band threshold passes through as the original object, so the
serialized text is only model-visible once a band triggers.
Type: Serializer | None Default: None
@classmethod
def combine(
    cls,
    capabilities: Sequence[AbstractCapability[AgentDepsT]],
) -> AbstractCapability[AgentDepsT]
Merge the configuration, with the later band winning a shared threshold, then re-derive from it.
_store, _bands, and _per_tool are derived in __post_init__, which merging skips, so
they are rebuilt from the merged configuration: a merged band list keeps the largest-first
order a single instance has, and a stated store is the one spills go to.
AbstractCapability[AgentDepsT]
@async
def before_run(ctx: RunContext[AgentDepsT]) -> None
Fail the run at its start when a band can spill but no store has a workspace to write to.
def get_toolset() -> AgentToolset[AgentDepsT] | None
Register the read_tool_result tool for reading spilled payloads on demand.
When spills are files in the run’s workspace, the tool steps aside for a tool of
FileSystem’s READ_FILE_KIND, which reads them too. Built once, so durable execution
sees the toolset it registered.
AgentToolset[AgentDepsT] | None
@async
def after_tool_execute(
    ctx: RunContext[AgentDepsT],
    *,
    call: ToolCallPart,
    tool_def: ToolDefinition,
    args: dict[str, Any],
    result: Any,
) -> Any
Reduce the tool result — both return_value and model-visible content.