Advisor
Give an executor model a way to consult a separate advisor model before it answers or commits to a decision.
While Pydantic AI Harness is on 0.x releases, the API may change between minor releases; when it does, deprecation warnings and release-note migration guidance tell you (or your agent) exactly how to upgrade. See the version policy.
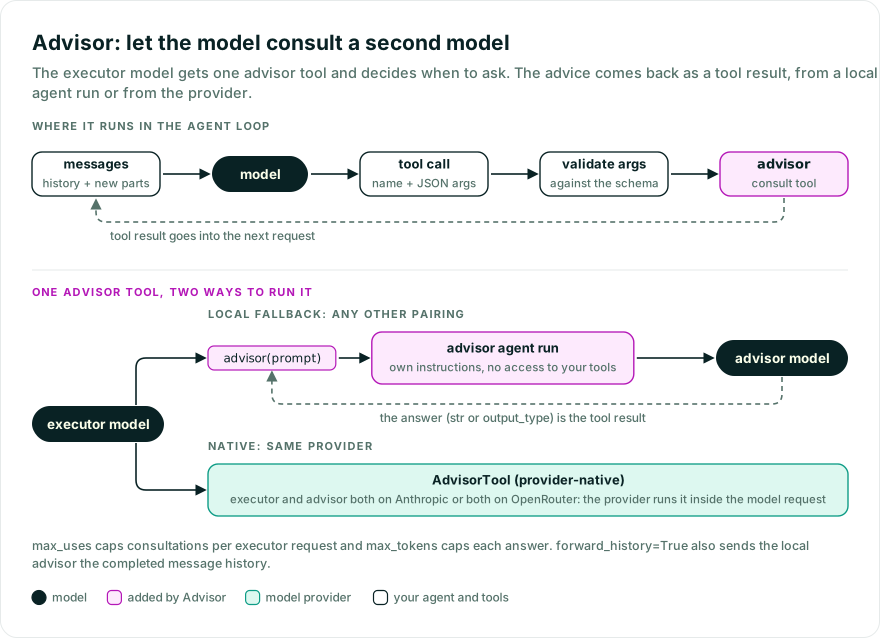
Pass the advisor model as the first argument. The model can be any model name or model instance accepted by Pydantic AI:
from pydantic_ai import Agent
from pydantic_ai_harness import Advisor

agent = Agent(
    'openai:gpt-6.1-sol',
    capabilities=[
        Advisor(
            'anthropic:claude-opus-5-5',
            max_uses=1,
            max_tokens=4096,
        )
    ],
)

result = agent.run_sync(
    'Design a zero-downtime database migration. Consult the advisor before choosing a plan.'
)
print(result.output)
The executor decides when to consult. Ask it explicitly in the user prompt or the agent’s instructions when a consultation is required.
Set output_type to the output specification you would pass to a Pydantic AI Agent, such as a Pydantic model, a scalar type, or NativeOutput(...). It defaults to str. The advisor model must support the selected output mode.
Provider-native advisor tools do not accept an output schema. A non-default output_type therefore selects local execution in auto mode; combining it with mode='native' raises ValueError.
from pydantic import BaseModel
from pydantic_ai import Agent
from pydantic_ai_harness.advisor import Advisor


class Decision(BaseModel):
    proceed: bool
    risk_score: float


agent = Agent(
    'openai:gpt-6.1-sol',
    capabilities=[Advisor('anthropic:claude-opus-5-5', output_type=Decision)],
)
The executor receives the validated object as the tool result. Once max_uses is used up, the tool returns a plain-text limit message instead.
Advisor exposes one logical tool through two execution paths, using Pydantic AI’s native-or-local tool selection:
- Native: when the executor and advisor are both on a compatible Anthropic provider, or both use OpenRouter, Pydantic AI’s provider-native
AdvisorToolruns the consultation. - Local fallback: every other pairing gets an
advisorfunction tool. Calling it runs a separate Pydantic AI agent with the configured advisor model.
In the default auto mode, native selection is conservative. The capability only reuses an explicit provider-qualified model name when the executor and advisor share a provider, so it does not guess how an Anthropic model ID maps to an OpenRouter catalog slug. For example:
from pydantic_ai_harness import Advisor

# Native for an Anthropic executor; local for OpenAI, Google, and other executors.
anthropic_advisor = Advisor('anthropic:claude-opus-5-5')

# Native for an OpenRouter executor.
openrouter_advisor = Advisor('openrouter:anthropic/claude-opus-4.8')
In auto mode, a Model instance runs locally and keeps its own provider, client, credentials, base URL, and instrumentation. A model name is resolved only when a consultation runs locally, so a native consultation uses the executor provider’s configuration. Native use also requires the executor model’s profile to support the advisor tool; otherwise auto falls back to local.
| Option | Default | Behavior |
|---|---|---|
model | required | Advisor model name or Model instance. |
mode | 'auto' | Execution policy: 'auto', 'native', or 'local'. |
output_type | str | Local advisor output specification. Non-default values require local execution. |
max_uses | None | Maximum consultations in one executor model request. Must be at least 1. |
max_tokens | None | Maximum output tokens for each consultation. Must be at least 1024. |
caching | None | Anthropic-native prompt-cache TTL: '5m' or '1h'. OpenRouter and the local fallback have no equivalent control. |
forward_history | False | Forward completed executor message history to local consultations. |
Use mode='native' when the consultation must stay inside the executor provider, or mode='local' when the configured advisor provider must receive a separate request. Native mode requires an anthropic:<model> or openrouter:<model> string and an executor on that same provider. A provider subclass that only changes its name, such as an AnthropicProvider subclass named claude-code, counts as the provider it extends. It does not fall back when the executor lacks support.
max_uses has the same per-request scope as Anthropic’s native tool and resets on the next request. On the local path, a call counts once its arguments validate, even if the consultation then fails. Parallel calls cannot exceed the cap. Without max_uses, the run’s usage limits bound local consultations within one request.
OpenRouter’s native tool ignores max_uses and applies its own fixed per-request limit. In auto mode, setting max_uses with an OpenRouter advisor therefore selects the local fallback. With mode='native', it raises ValueError.
forward_history does not affect native-versus-local selection. The current response, including partial text and unresolved tool calls, is not forwarded, so the consultation prompt still needs to contain the complete current question.
String model configurations can be loaded from YAML or JSON agent specs by passing Advisor in custom_capability_types. Runtime Model instances and custom output specifications remain Python-only.
The context depends on the execution path:
| Path | Advisor context |
|---|---|
| Anthropic native | The provider supplies the full transcript, including system instructions, tool definitions, earlier turns and results, and executor text produced so far. |
| OpenRouter native | The executor supplies a consultation prompt. Pydantic AI configures forward_transcript=false. |
| Local fallback | The executor supplies a consultation prompt through the advisor function tool. With forward_history=True, the advisor also receives completed executor message history. |
The local advisor has its own instructions and no access to the executor’s dependencies, tools, or toolsets. For portable behavior, tell the executor to put the question and all relevant evidence in its consultation prompt; the local tool description asks for this too.
Local consultations go to the advisor model’s provider. With forward_history=True, that request also carries the executor’s earlier messages as structured message history, including any system_prompt parts, its tool calls, and their results. Native consultations stay with the executor’s provider.
Local advisor requests share the parent run’s RunUsage and UsageLimits, so their requests and tokens count toward the agent tree’s normal limits. A local advisor run is also filed under the parent run’s conversation_id, so its requests and spans group with the conversation it advises. Native providers report advisor usage according to their own protocol. Anthropic records advisor-specific values in RequestUsage.details, while OpenRouter exposes aggregate server-tool counts in response provider details.
Invalid option combinations fail when Advisor is constructed. Executor and provider compatibility is validated when a run prepares its model request. Anthropic reports native advisor errors as tool results so the executor can continue. If a local advisor produces invalid model behavior, the executor receives a normal tool retry, matching Pydantic AI’s other subagent-backed tools. Local model resolution, authentication, provider, request, and usage-limit errors otherwise propagate and can stop the run. When a local call exceeds max_uses, the tool returns a bounded message telling the executor to continue without more advice.
Advisor emits no spans of its own. With Pydantic AI instrumentation enabled globally, for example through logfire.instrument_pydantic_ai(), a local consultation appears as an agent run named advisor; per-agent instrument= on the executor does not reach that run. A native consultation is part of the executor’s model request.
The advisor tool is always visible and is not deferred through Tool Search. It reserves the tool name and toolset ID advisor. An agent has one advisor, so two Advisor capabilities merge into one. An option left at None (max_uses, max_tokens, caching) takes the other instance’s value, two list output_types are combined, and every other option takes the later instance’s value. If the merge gives an OpenRouter Advisor in mode='native' a max_uses, which no single Advisor accepts, max_uses is ignored with a HarnessDeprecationWarning; this will raise UserError in a future release.
During streaming, the executor stream pauses while an advisor consultation runs and resumes when the completed advice is available. The local fallback does not splice the advisor model’s token deltas into the executor stream.
Native advice is compatible with durable execution because it remains part of the executor model request. Local execution cannot yet preserve the same semantics across every durable backend. Temporal and Prefect can checkpoint the returned advice, but changes to the activity-local or task-local RunUsage do not merge back into the outer run. DBOS checkpoints each local consultation, so workflow replay reuses the recorded advice.
Under Temporal and Prefect, use mode='native' with a supported provider. Local execution there, including an auto fallback, is unsupported. Advisor cannot detect durable runs, because Pydantic AI does not yet expose a public durable-context contract, so it does not reject local execution in them.
Bases: NativeOrLocalTool[AgentDepsT]
Let an agent consult another model through a provider-native tool or local fallback.
In auto mode, Advisor uses Pydantic AI’s native AdvisorTool when an
explicit provider-qualified model name matches a compatible Anthropic or
OpenRouter executor. On every other model, it exposes an advisor function
tool backed by a separate Pydantic AI agent.
from pydantic_ai import Agent
from pydantic_ai_harness.advisor import Advisor

agent = Agent(
    'openai:gpt-5.4',
    capabilities=[Advisor('anthropic:claude-opus-4-8')],
)
One-off: an agent has one advisor, so the id is fixed.
Two Advisor capabilities resolve to one via
combine.
Type: str | None Default: 'advisor'
Output specification for local consultations, defaulting to text.
A non-default specification selects local execution in auto mode and is
incompatible with native mode. Successful consultations return the
validated output directly to the executor.
Type: OutputSpec[object] Default: output_type
The model to consult.
Accepts the same model names and model instances as Agent. In auto
mode, model instances use local execution so their provider configuration
is preserved.
Type: ModelSelection Default: model
How advisor consultations are executed.
auto uses a native advisor only for an explicit same-provider model name.
native requires a provider-native advisor, and local always runs a
separate Pydantic AI agent.
Type: Literal[‘auto’, ‘native’, ‘local’] Default: mode
Maximum consultations in one executor model request.
The limit resets on the next executor request. OpenRouter’s native advisor does not honor this option, so setting it selects the local fallback there.
Type: int | None Default: max_uses
Maximum output tokens for each advisor consultation.
Values below 1024 are rejected so the setting remains valid on every native and local execution path.
Type: int | None Default: max_tokens
Anthropic-native advisor prompt-cache TTL.
OpenRouter and the local fallback have no equivalent cache control.
Type: Literal[‘5m’, ‘1h’] | None Default: caching
Whether local consultations receive the executor’s completed message history.
Native execution keeps the provider’s transcript behavior unchanged.
Type: bool Default: forward_history
@classmethod
def from_spec(
    cls,
    model: KnownModelName | str,
    *,
    mode: Literal['auto', 'native', 'local'] = 'auto',
    max_uses: int | None = None,
    max_tokens: int | None = None,
    caching: Literal['5m', '1h'] | None = None,
    forward_history: bool = False,
    **kwargs: Any,
) -> Advisor[Any]
Build from an agent spec, covering the fields a spec can express.
Every JSON-expressible parameter is named because that signature is what core reads to
generate the spec’s JSON schema. A spec names the model by string. output_type has no
JSON form, so it is passed through **kwargs, which the schema omits.
Advisor[Any]
@classmethod
def combine(
    cls,
    capabilities: Sequence[AbstractCapability[AgentDepsT]],
) -> AbstractCapability[AgentDepsT]
Merge the fields, then rebuild the native factory and local tool from the merged result.
Both are built in __init__ from one instance’s configuration, so the inherited merge alone
would send the later instance’s settings while the merged fields report the union.
AbstractCapability[AgentDepsT]
@async
def for_run(ctx: RunContext[AgentDepsT]) -> Self
Return a fresh capability with local usage isolated to this run.
@async
def after_model_request(
    ctx: RunContext[AgentDepsT],
    *,
    request_context: ModelRequestContext,
    response: ModelResponse,
) -> ModelResponse
Reset the local consultation allowance for each executor response.